DeepSeek Harness Plugins · Model Inference
Plugins that extend DeepSeek Harness (DSH) with vision, workflows, memory, web tools and more.
A local daily check-in and token/cost ledger for DSH that tracks model usage per provider/model without network uploads, with a draggable web widget.
Optimizes image requests for DSH agent loops with compression, content-address deduplication, retention policies, and live observability reporting.
Enables DeepSeek to understand images by describing pasted screenshots or local JPEG/PNG/WebP files via MindSee, without switching to a vision model.
Voice input for DSH: tap the mic, speak, and text fills the input box. Local Whisper transcription with simplified-Chinese output, anti-hallucination, and zero cloud dependency.
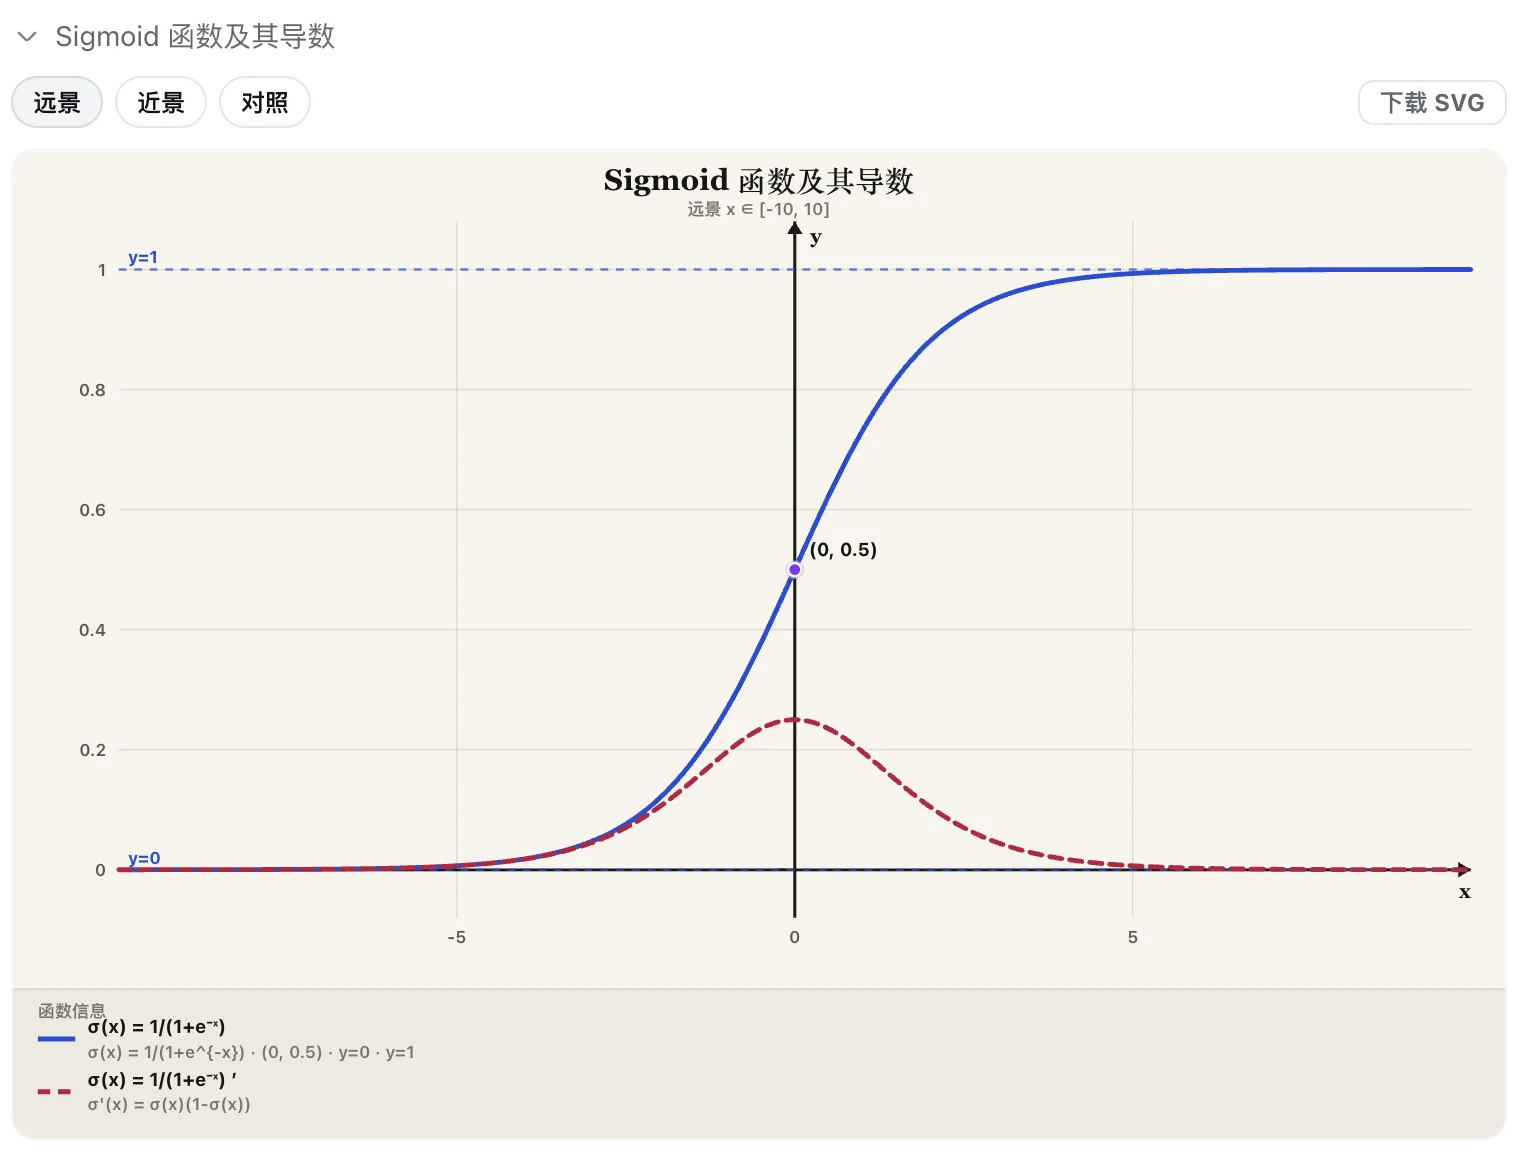
Plot function graphs as interactive cards with zoom and comparison views and SVG export, or render existing workspace SVG images directly in the conversation.
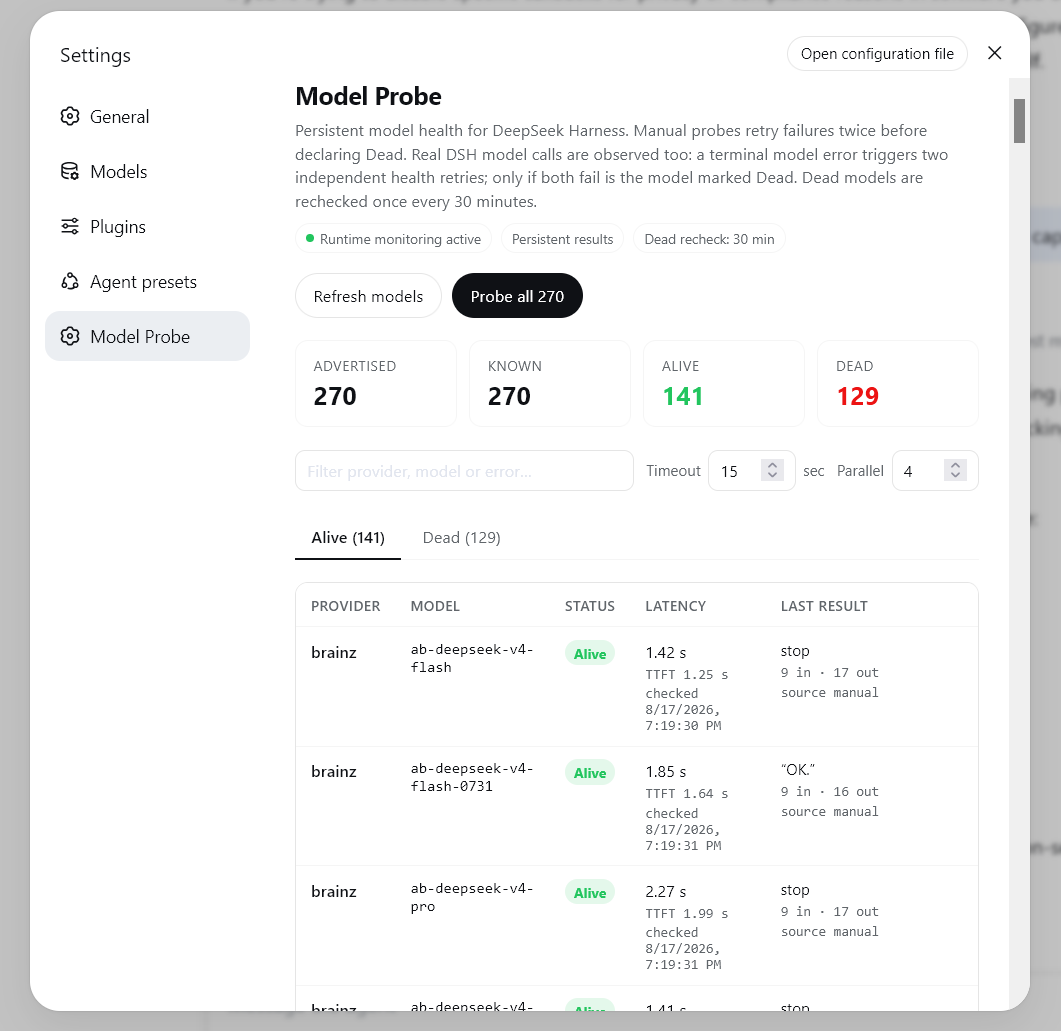
Persistent model health monitoring for DSH Web UI: auto-discovers, probes, and tracks Alive/Dead status per provider-model, with live health badges and health-first ordering across all model pickers.
Compresses verbose tool error tracebacks in long agent sessions, keeping only the first N message lines with an elision marker to reduce context rot.
A read-only runtime inspector for DeepSeek Harness that reveals the active runtime base, session capabilities, model context, and lifecycle resources without modifying any configuration.
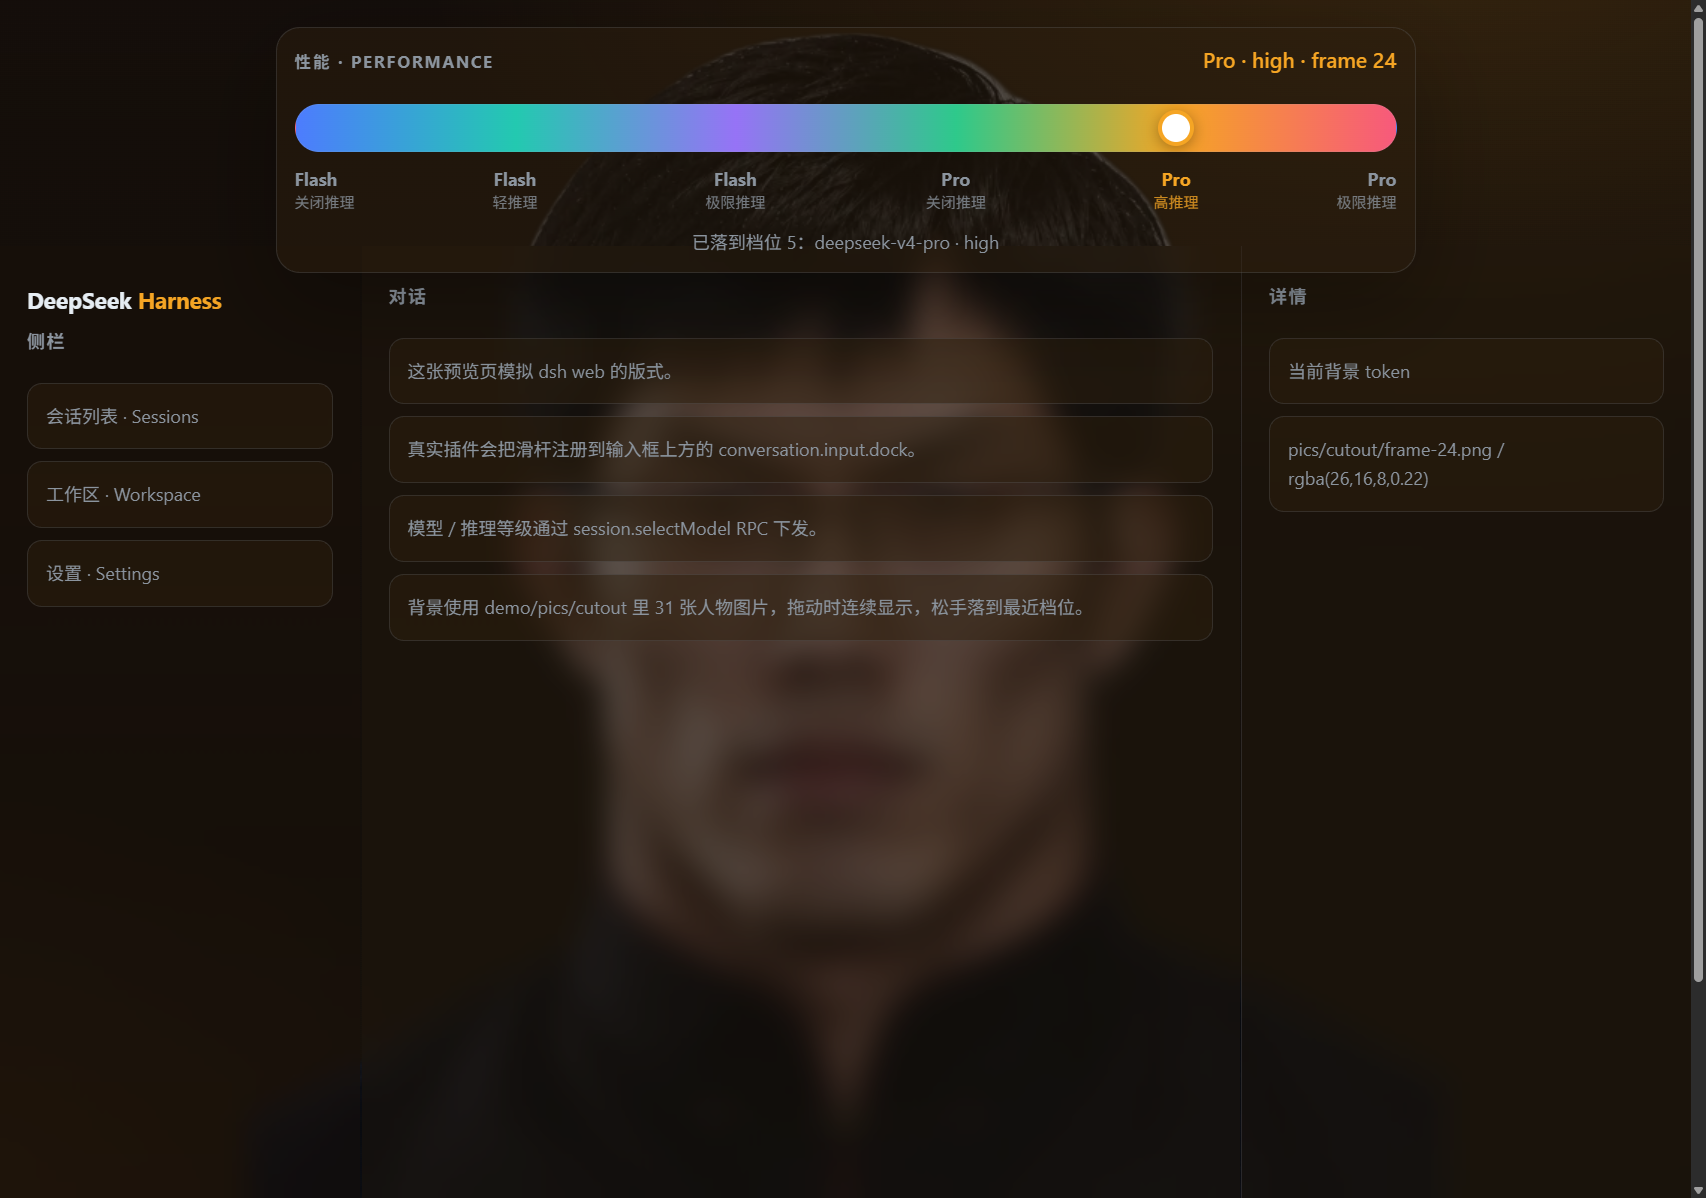
A Codex-style 6-level slider for DeepSeek Harness that maps each level to a model and reasoning effort, with 31 animated character-background frames on drag.
Estimate memory, latency, throughput, and power for LLM deployment with automatic TP/PP/DP strategy selection across 38 models and 20 GPU/NPU types.
Bridges vision capability to text-only models by auto-converting images into text descriptions, with multi-backend routing and 26 visual tools.
Gives text-only LLMs dual-mode visual understanding by supporting direct image pasting in chat and active tool calls on local files, leveraging a vision model for OCR and content recognition.