DeepSeek Harness Plugins · Model Inference
Plugins that extend DeepSeek Harness (DSH) with vision, workflows, memory, web tools and more.
Give text-only DeepSeek-V4-Pro image understanding by transcribing via deepseek-v4-flash-vision-exp, with zero extra dependencies, no model switch, and no second API key.
Adds a one-click prompt optimization button to the DSH input box, rewriting your draft into a clearer prompt with undo, side-by-side comparison, and zero chat interruption.
A DeepSeek Harness model-inference plugin that enhances chat dialogue experience.
Bridges the Yuandian (Chineselaw) open-platform MCP endpoint into DeepSeek Harness, shipping four official legal-data skills for statute, case, corporate, and securities-compliance retrieval with OAuth and API Key authentication.
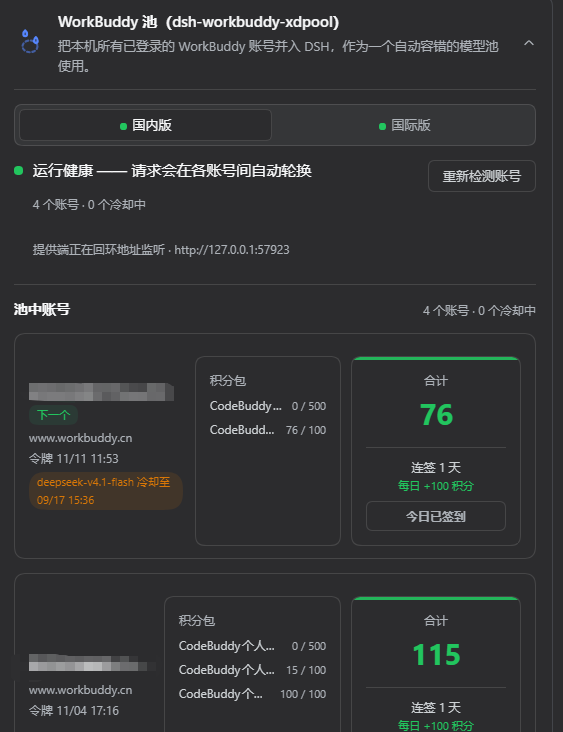
Zero-config pool of all WorkBuddy desktop accounts with automatic 429 failover—every logged-in account joins the pool and requests auto-route to the next healthy one on rate-limit.
Iris is a multimodal production runtime for DeepSeek Harness, providing image generation, video creation, speech synthesis, and visual understanding across multiple providers.
Configure reasoning efforts, modalities, compatibility toggles, and request headers for custom models directly in the Models settings card, with automatic session-based header injection and no manual file edits required.
Forces the model to reply in a specified language (Simplified Chinese by default) in DeepSeek Harness, switchable at runtime via tools while preserving code and proper nouns.
Exposes your Open WebUI models as an OpenAI-compatible API for DeepSeek Harness Desktop via a local reverse proxy, with a built-in usage dashboard and one-click model sync.
A node-based visual video director plugin for DeepSeek Harness that links script, image, audio, and video generation into a single canvas with local Ollama and ComfyUI workflows.
SupaNexus platform core: brand styling, OAuth quick setup, dual-region model access, and app plugin marketplace.
Adds a Local Models tab to dsh Web GUI for picking GGUF files, tuning context and speculative decoding, monitoring live VRAM, and one-click loading via llama-server as an LLM provider.