DeepSeek-Harness-Video-Director
Run the following command in DeepSeek Harness:
dsh plugin install chiphoton/DeepSeek-Harness-Video-Director
Paste the following prompt into your AI chat to install this plugin:
Run dsh plugin install chiphoton/DeepSeek-Harness-Video-Director in the DeepSeek Harness terminal to install this plugin; the source repository is available at https://github.com/chiphoton/DeepSeek-Harness-Video-Director .
About this plugin
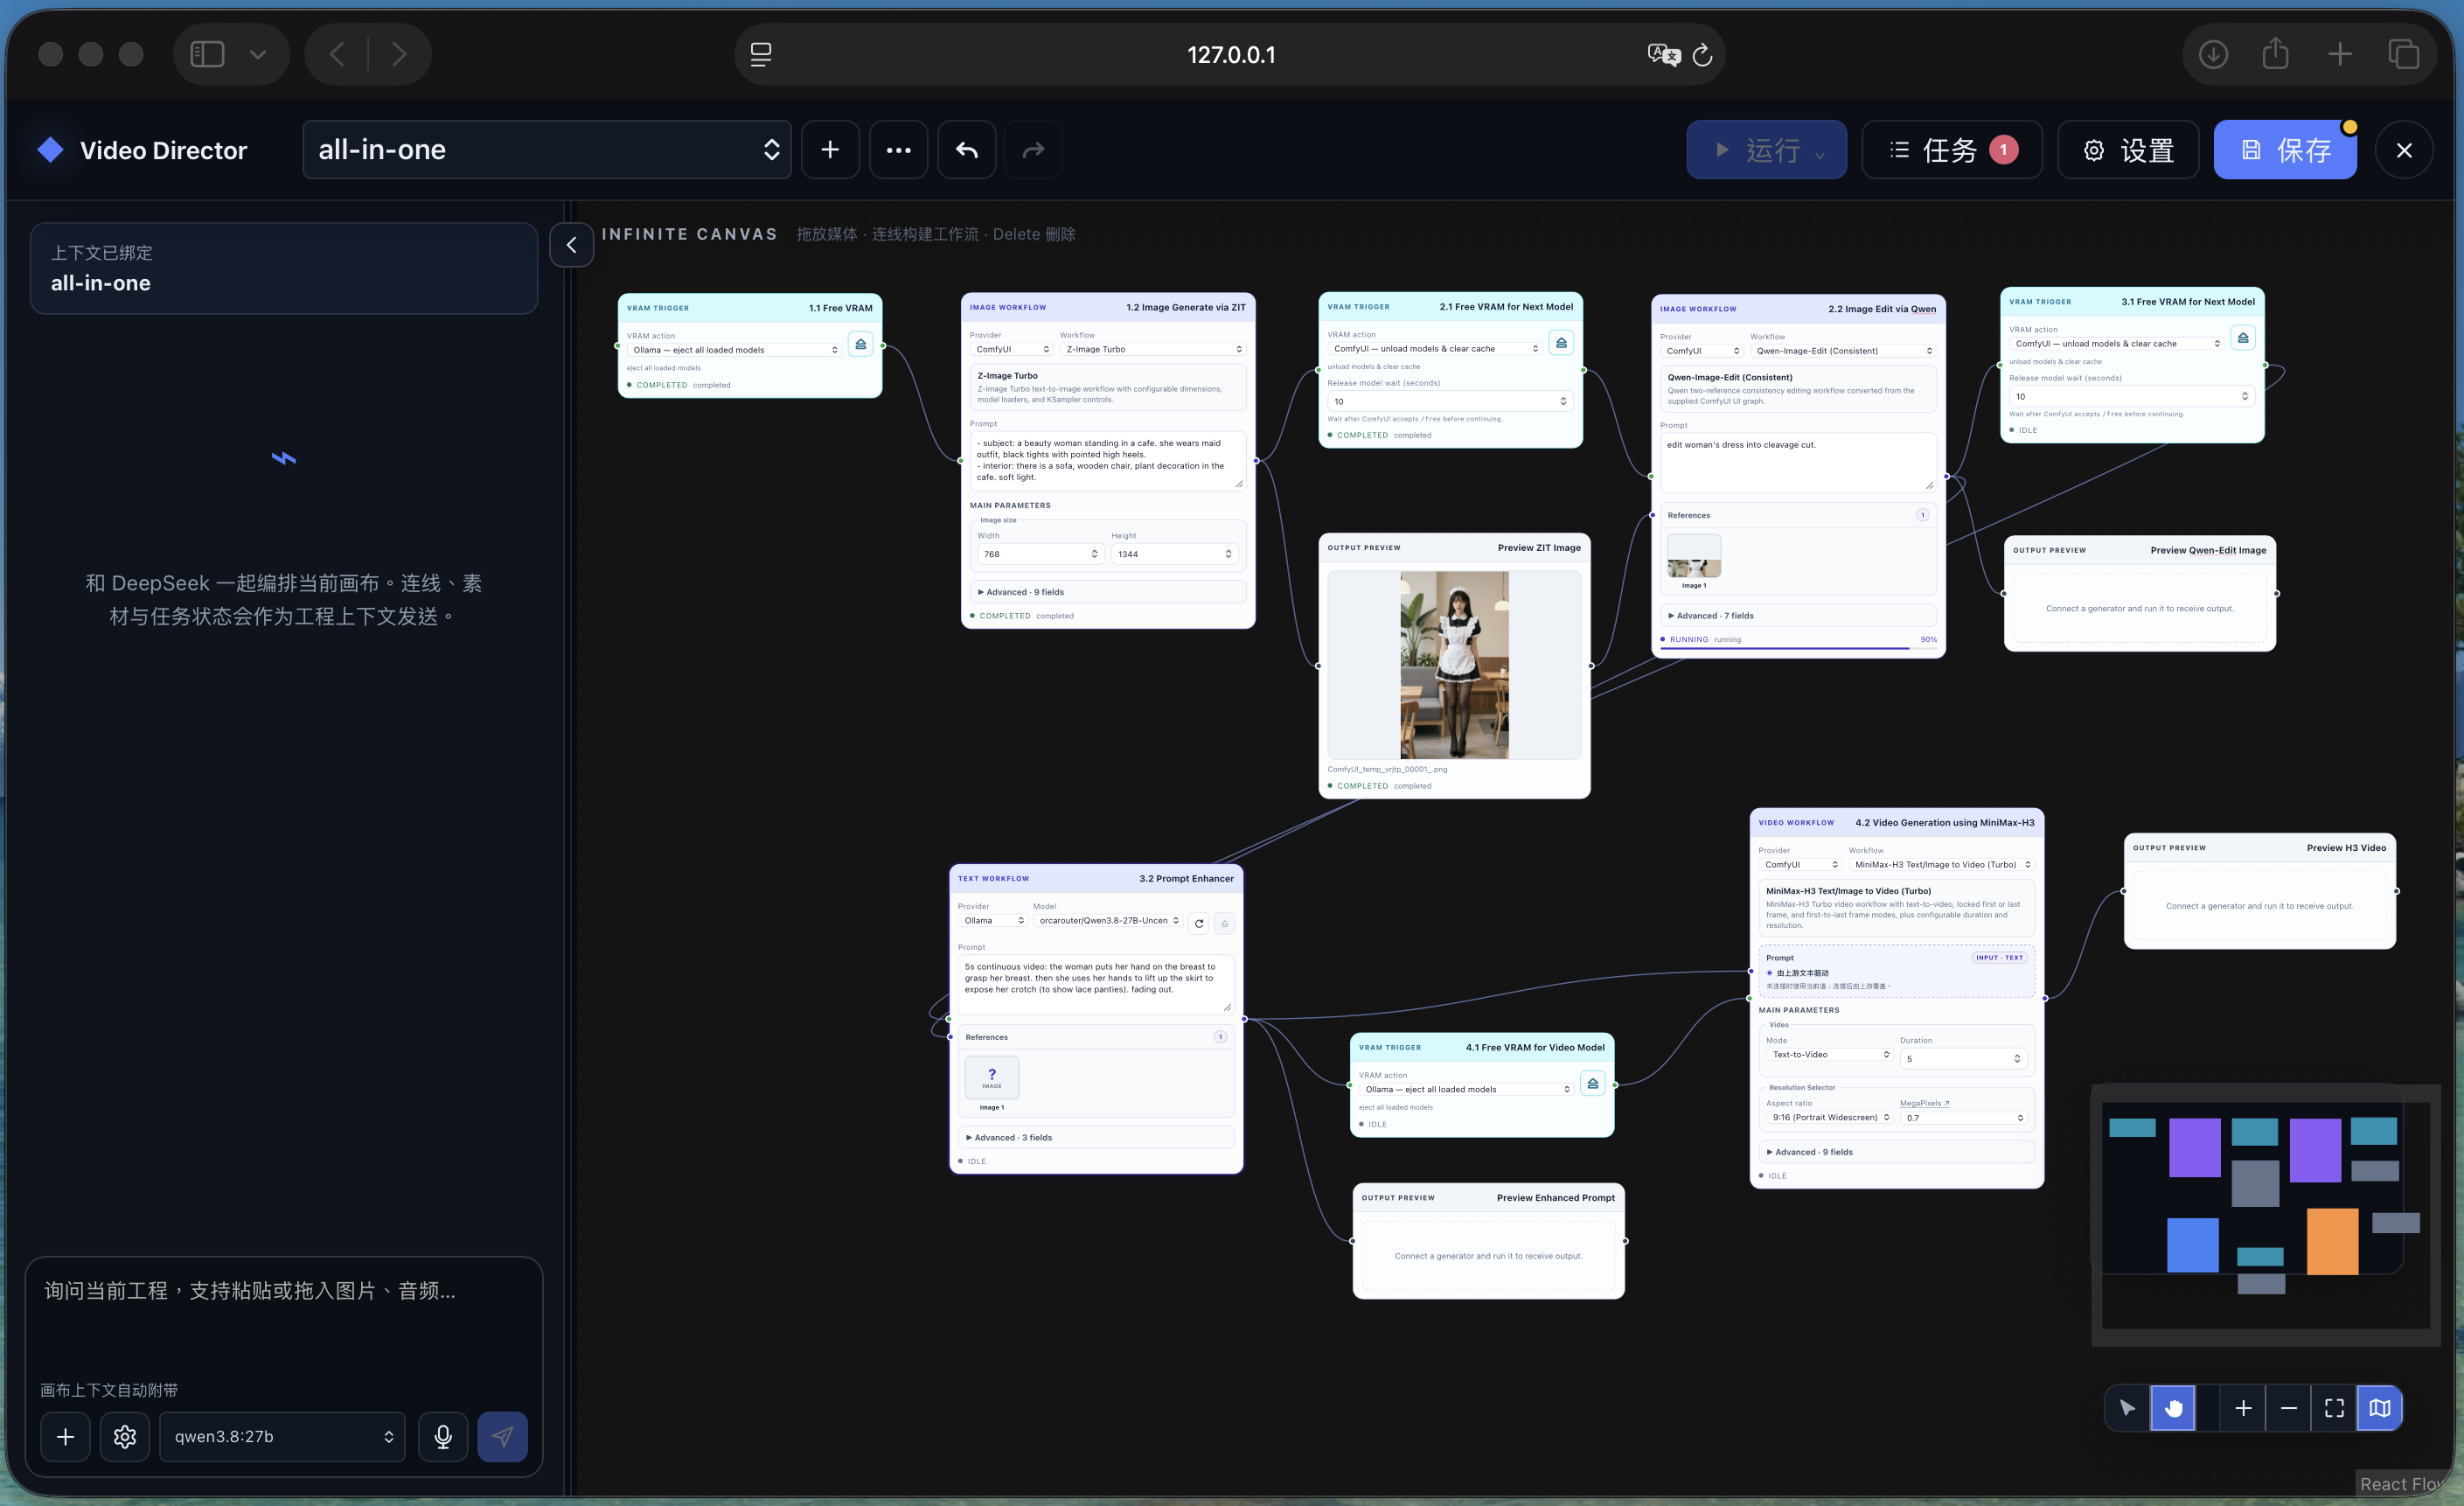
Multimodal video production typically means juggling text generation, image processing, audio synthesis, and video rendering across separate APIs, hand-stitching prompts, and debugging provider configurations one by one. Video-Director pulls that entire chain onto a single, infinitely scrollable canvas: drop in text, image, audio, or video nodes, link compatible outputs to inputs, and hit Run to execute the whole pipeline without writing a single manual request.
It ships with ready-to-use workflows for prompt enhancement, image processing, MiniMax-H3 text-to-video and image-to-video, and H3 audio, while letting you mix Ollama, ComfyUI, OpenAI-compatible endpoints, and Codex Plan within the same project. For creators who want a fully local pipeline, the bundled Qwen3.8-27B and MiniMax-H3 paths keep every stage of generation on hardware you control, with no external cloud dependency. A bundled skill also converts trusted ComfyUI workflow JSON into reusable, declarative Custom Nodes, extending the canvas without writing code.
It is aimed at independent creators, small studios, and developers who want to shift video production from assembling API calls to connecting nodes-especially teams that value local controllability, refuse lock-in to a single cloud provider, and still need a low-barrier on-ramp for new team members.
Screenshots
Use Cases
- Run a full generation chain from prompt enhancement to video rendering entirely on local Ollama and ComfyUI
- Convert trusted ComfyUI workflows into reusable Custom Nodes and extend the canvas without writing code
- Mix Ollama, ComfyUI, and OpenAI-compatible endpoints in one project to composite multimodal assets
Best For
- Independent creators who want fully local video generation without external cloud services
- Small studios深耕 the ComfyUI ecosystem who want to unify scattered workflows onto a single canvas
- AI developers who need multi-provider mixing and a low-friction onboarding path for their team
Related Plugins
A unified suite combining hot runtime injection, task-aware thinking-mode routing, and a graded session protocol with red-team gates to sustain model diligence across long-horizon inference.

ModLens is a vision plugin for DeepSeek Harness that gives text-only models sight by reading images pasted directly into chat, with zero-config setup and multiple vision engines.

On-demand vision for text-only DeepSeek Harness agents: built-in free keyless vision chain and 14 vision tools, routing image turns as tool calls to vision models with pixel fidelity, no Python needed, one-command install.

Give text-only models in DeepSeek Harness eyes, enabling image Q&A, long-screenshot OCR, UI restoration, and GUI visual tasks.