dsh-cache-safe-tool-result
Run the following command in DeepSeek Harness:
dsh plugin install DoctorxPriestess/dsh-cache-safe-tool-result
Paste the following prompt into your AI chat to install this plugin:
Install the plugin in DeepSeek Harness by running dsh plugin install DoctorxPriestess/dsh-cache-safe-tool-result; the source code is available at https://github.com/DoctorxPriestess/dsh-cache-safe-tool-result
About this plugin
DSH's prompt cache is a prefix cache: the provider reuses it only while the request's leading tokens are byte-identical to what it saw before. Yet the built-in tool-result pruner truncates oversized results in place, rewriting nodes that a provider request has already delivered. A single such rewrite invalidates everything after that node, re-billing the entire tail as uncached input. Production logs measured on the two sessions behind this plugin show single jumps of 50,000 to 311,788 uncached tokens, adding up to a staggering cost in long sessions.
dsh-cache-safe-tool-result enforces one invariant: a tool result may be compressed before it first enters the session surface, but once a provider request has carried it, its bytes never change again. The FIRST-PASS half mounts on the tools/post-execute waterfall and truncates over-budget results before they are appended, so a surface node is born in its final form. The GUARD half replaces the toolResultPruner service, refusing to rewrite any already-delivered node while still pruning undelivered ones normally. Both halves use only public DSH and Cordis extension points; no node_modules file is touched.
It is aimed at DSH users who run long sessions heavy with tool calls (code generation, file I/O, API queries) and want to maximise cache hit rates. Regression tests over two real production sessions confirm a 99.7% hit rate inside warm windows, refuse every recorded in-place rewrite, and keep session logs byte-stable across repeated passes, all without contacting a provider.
Use Cases
- Long sessions with heavy tool calls suffering from declining cache hit rates
- The built-in pruner rewriting delivered nodes and spiking uncached token costs
- Optimising DSH cache-prefix behaviour without modifying harness source code
Best For
- Developers running long DSH sessions with heavy tool-call workloads
- Tech leads tracking prompt cache hit rates and API token spend
- Plugin developers customising DSH behaviour without touching node_modules
Related Plugins

Memory layer for coding agents that indexes local session history and auto-recalls relevant context before edits, commands, and failures, with no manual search needed.
Traceable, searchable cross-session memory for AI agents that turns conversation knowledge into a typed knowledge graph and recalls relevant subgraphs instead of replaying full history, natively integrated with DeepSeek Harness.
Gives DSH AI cross-session long-term memory, to-do and skill management, plus multi-session orchestration, external AI delegation, and an infinite canvas that grows with you.
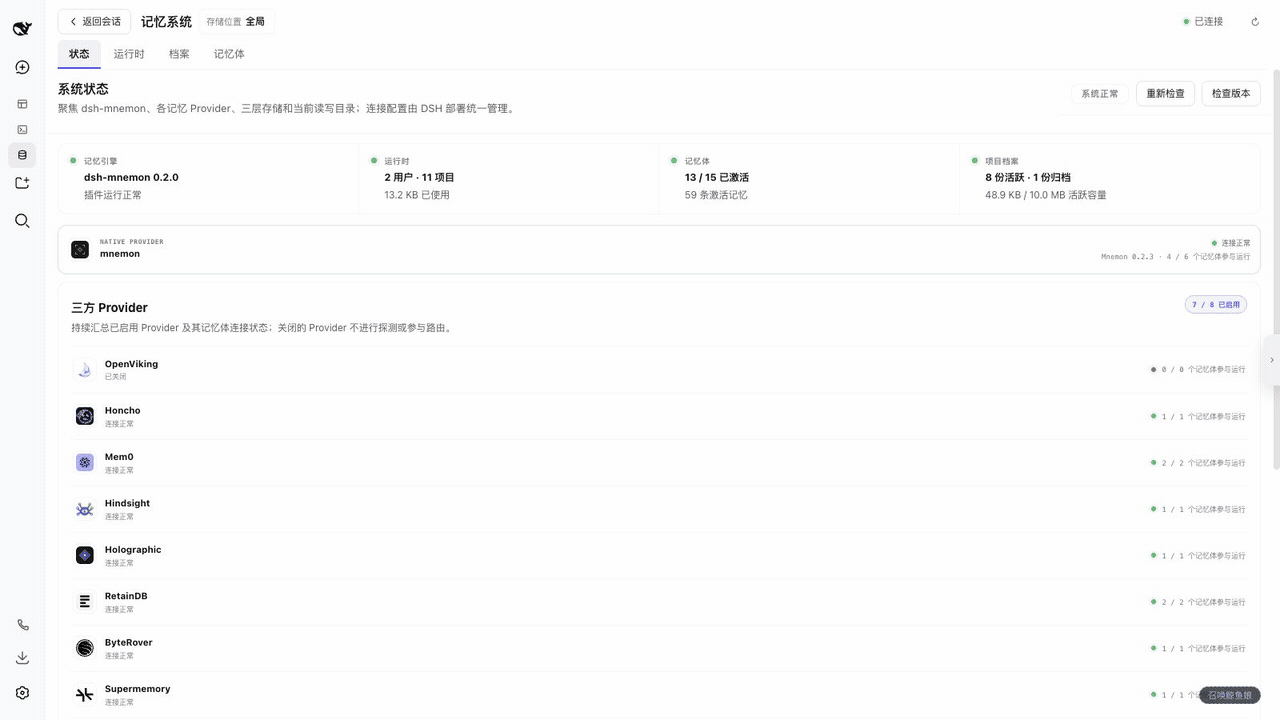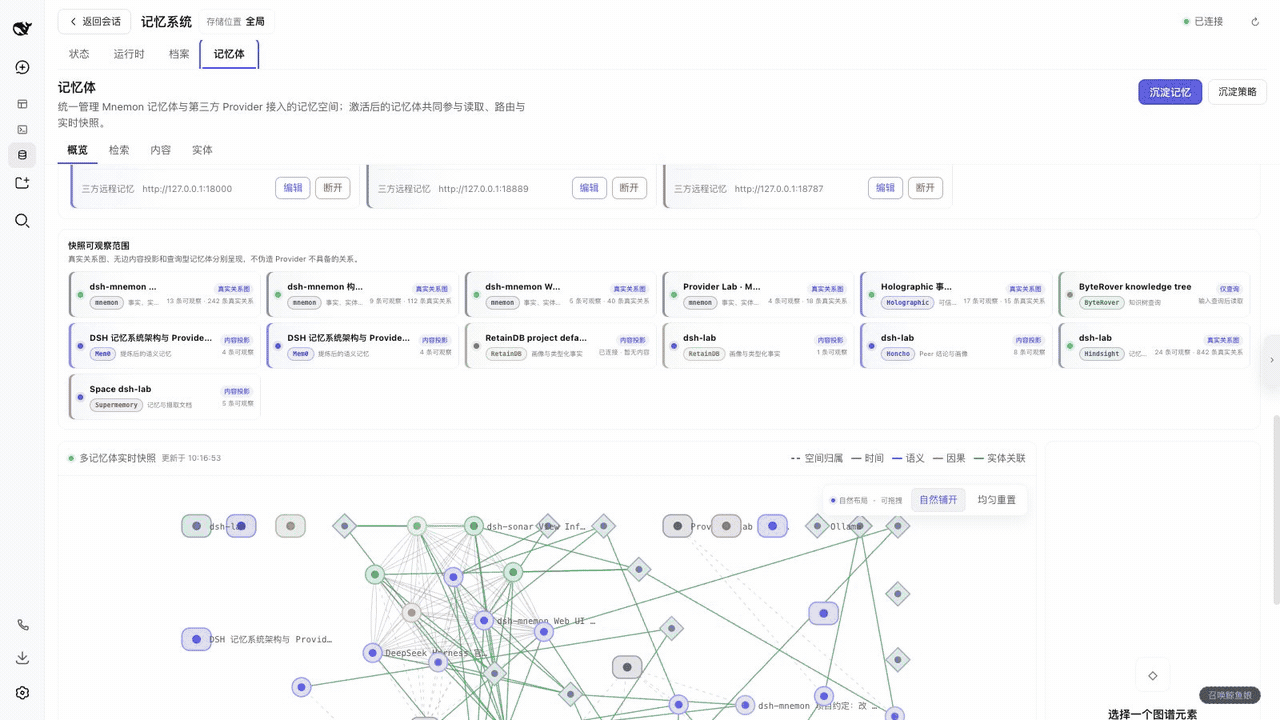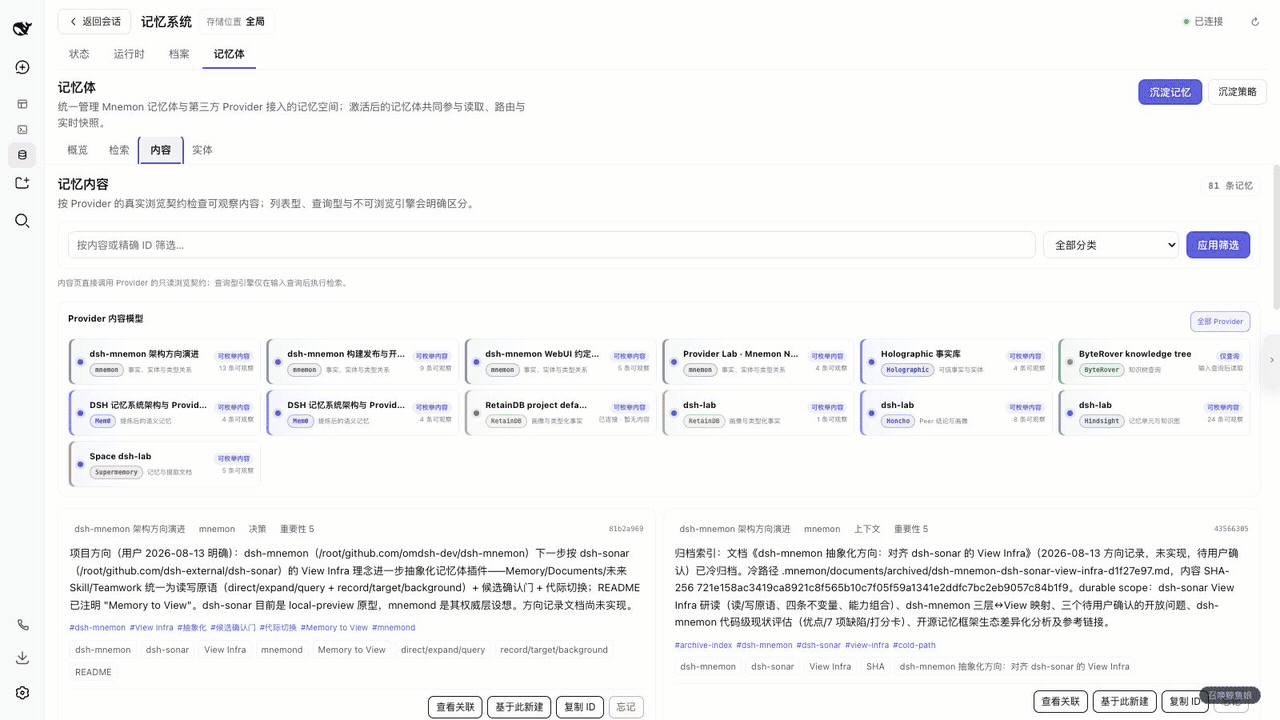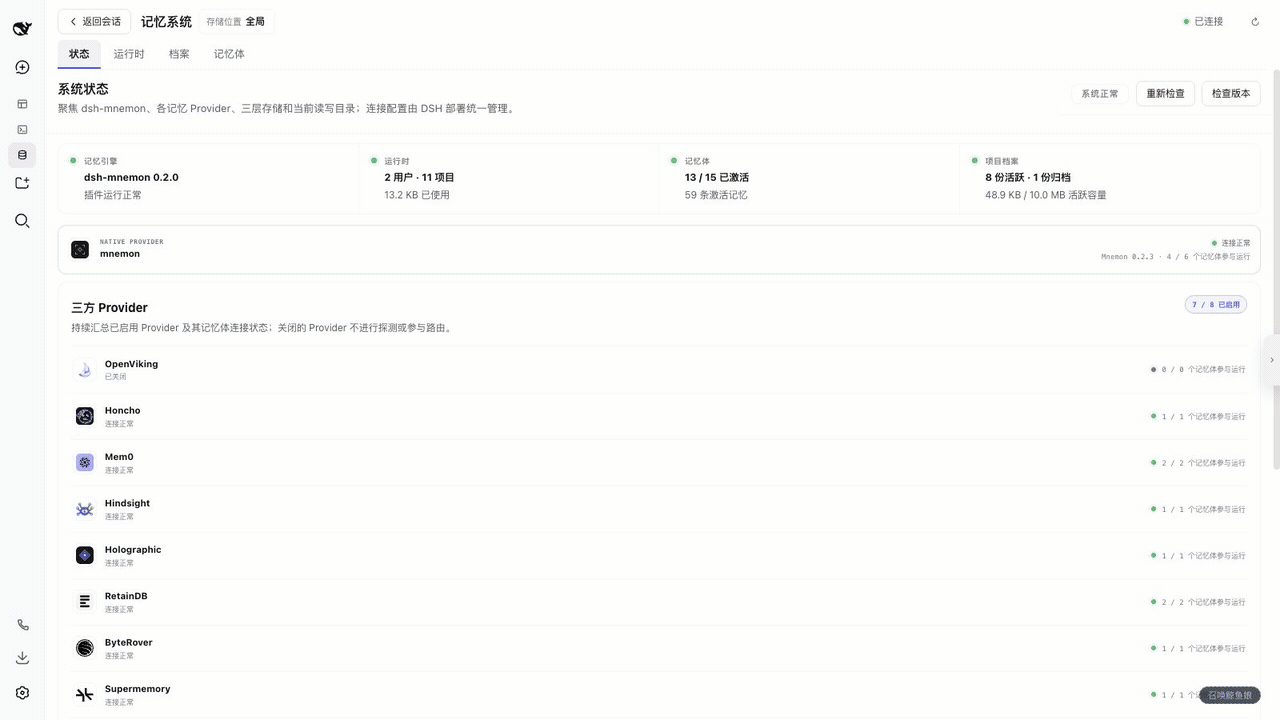
dsh-mnemon is a three-tier, pluggable, Agent-driven memory system for DeepSeek Harness, combining Runtime memory, Project Documents, and replaceable Memory Spaces with nine long-term providers.