dsh-infinite-context
Run the following command in DeepSeek Harness:
dsh plugin install chocobo77/dsh-infinite-context
Paste the following prompt into your AI chat to install this plugin:
Run dsh plugin install chocobo77/dsh-infinite-context in the DeepSeek Harness terminal to install; source is available at https://github.com/chocobo77/dsh-infinite-context
About this plugin
Long sessions are the daily reality for many DSH users, but a finite context window means early discussion details, project conventions, and debug context vanish the moment tokens run out. Local models often have only a few K of window, and a single extended-thinking expansion can blow past the entire budget. DSH itself only compacts reactively after the API returns CONTEXT_WINDOW_EXCEEDED, which is too late. dsh-infinite-context elevates memory management to a first-class plugin-layer capability, letting sessions proactively and progressively top up before the ceiling is hit, turning long conversations into a genuinely usable workflow.
The core mechanism is a three-tier memory pyramid: recent turns are kept verbatim, middle-round dialogue is LLM-summarized, and far history is consolidated into refined checkpoints, all persisted in SQLite so memories survive restarts. The compression trigger line is derived dynamically from the routed model REAL window. Local models are probed via Ollama, llama-server, or OpenAI-compatible endpoints to read the server actual runtime context, and the effective window is the minimum of declared and probed values, guaranteeing compaction fires before the true ceiling, not after. The mid-thinking guard is especially critical: the plugin wraps the agent LLM stream, measures input plus output block by block, and when the dynamic line is approached it injects an overflow signal, triggers durable compaction, then retries with headroom. The model gets stopped, compacted, and re-thinks, instead of wasting an entire doomed generation. Semantic retrieval splices the most relevant top-K memories into context each turn, three-layer dedup prevents duplicate ingestion, and a four-class structured index makes memories auditable and forgettable.
Two user profiles benefit most. First, developers who regularly work through large codebases or lengthy documents where conversations easily run dozens of rounds and losing early context means re-explaining everything from scratch. Second, heavy local-model users whose windows are small and whose thinking phases are long, where real-window awareness plus early compression is the critical combo. If you want DSH long sessions to have memory like a human rather than a goldfish, this plugin is worth a look.
Use Cases
- Early conversation context is lost as the window fills, requiring automatic summarization to keep continuity
- Local models with only a few K of window overflow during deep thinking, needing mid-generation compaction
- Reusing project memory and conventions across sessions instead of re-explaining context each time
Best For
- Developers regularly working through large codebases or lengthy documents
- DSH users running local models via Ollama, llama.cpp, or LM Studio
- Teams that want persistent, auditable memory across long DSH sessions
Related Plugins

Memory layer for coding agents that indexes local session history and auto-recalls relevant context before edits, commands, and failures, with no manual search needed.
Traceable, searchable cross-session memory for AI agents that turns conversation knowledge into a typed knowledge graph and recalls relevant subgraphs instead of replaying full history, natively integrated with DeepSeek Harness.
Gives DSH AI cross-session long-term memory, to-do and skill management, plus multi-session orchestration, external AI delegation, and an infinite canvas that grows with you.
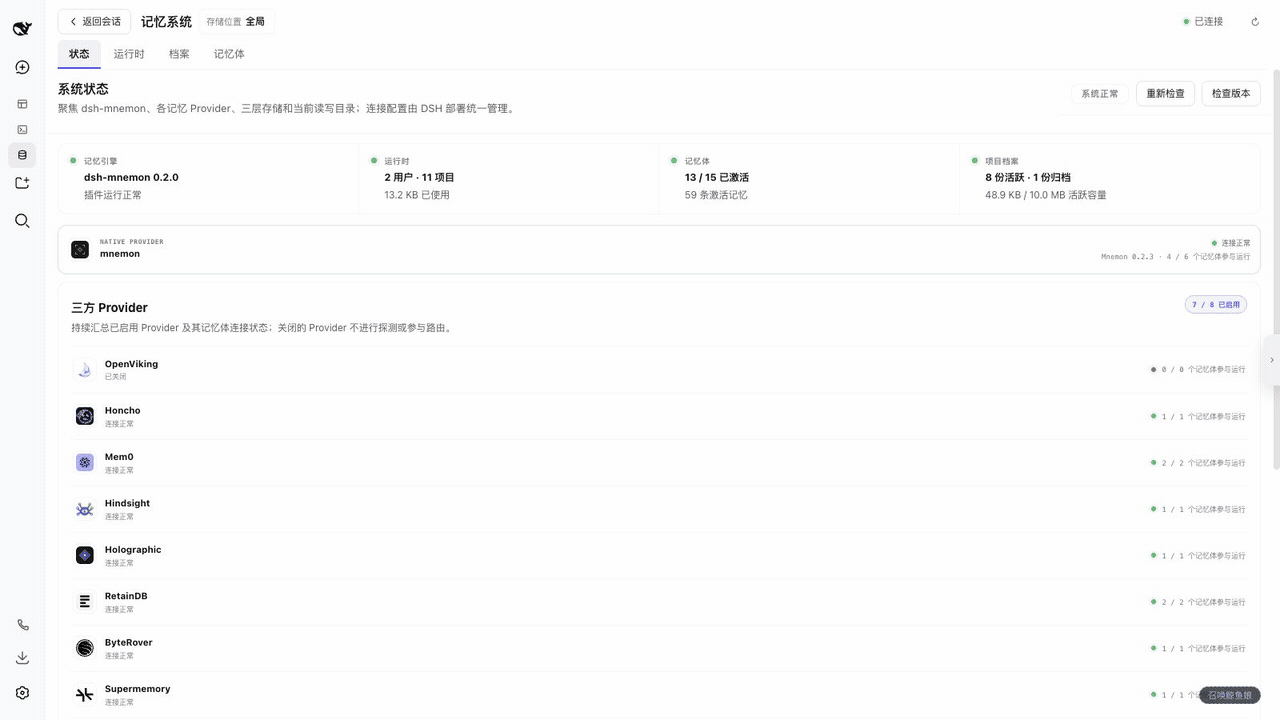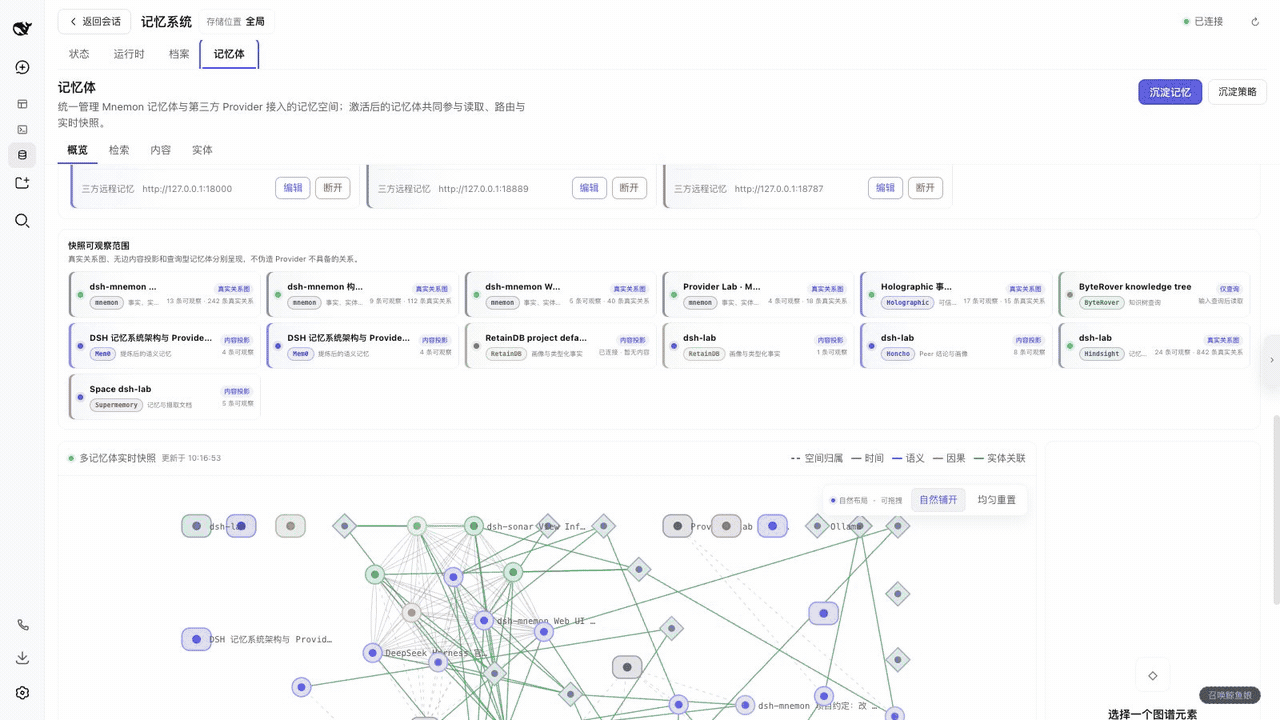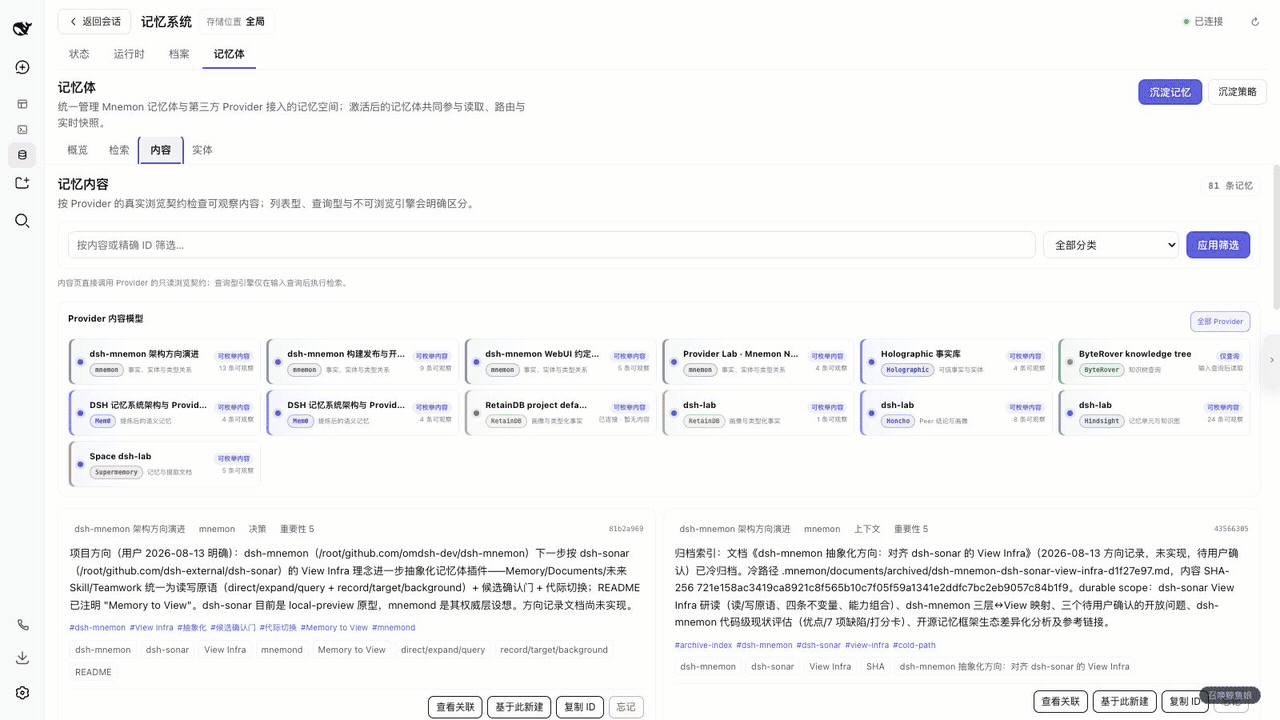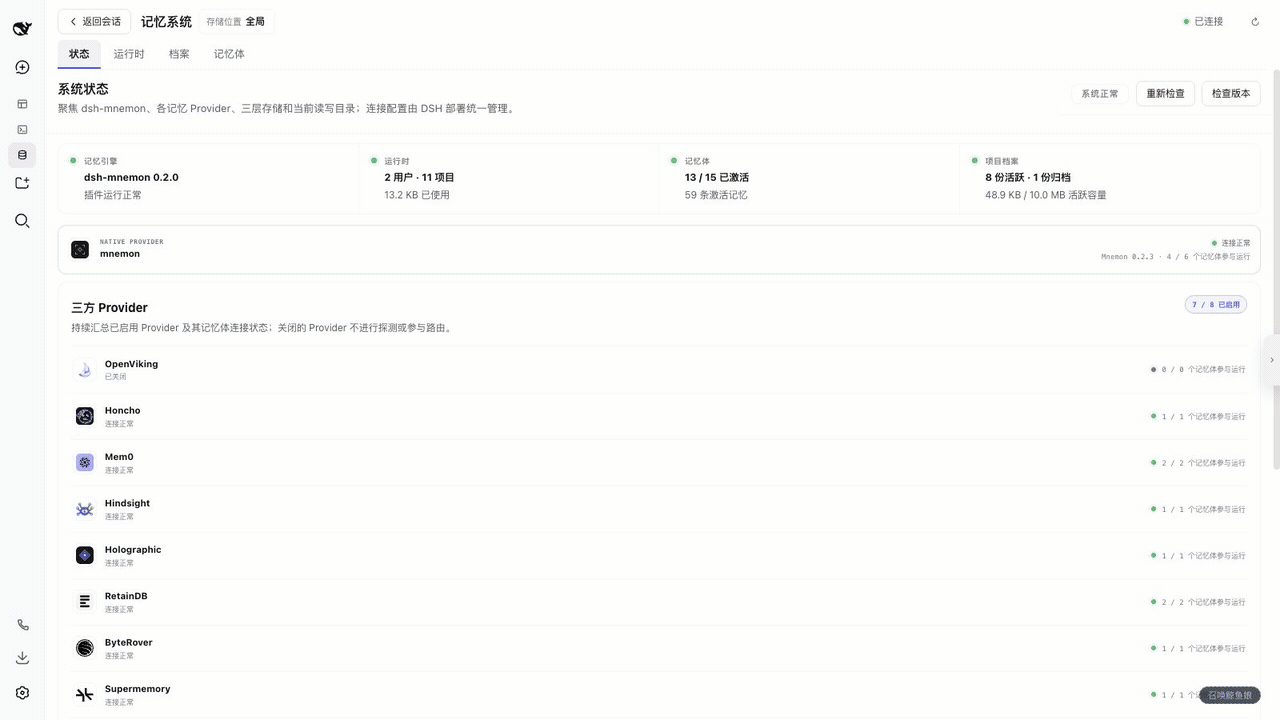
dsh-mnemon is a three-tier, pluggable, Agent-driven memory system for DeepSeek Harness, combining Runtime memory, Project Documents, and replaceable Memory Spaces with nine long-term providers.