dsh-plugin-om
Run the following command in DeepSeek Harness:
dsh plugin install FanetheDivine/dsh-plugin-om
Paste the following prompt into your AI chat to install this plugin:
Run dsh plugin install FanetheDivine/dsh-plugin-om in your DeepSeek Harness terminal to install this plugin; the source repository is https://github.com/FanetheDivine/dsh-plugin-om .
About this plugin
Long-running DSH sessions fill the context window quickly, and naive truncation throws away information you still need. dsh-plugin-om adopts an Observational Memory strategy: before each agent step it automatically compresses earlier messages into summary blocks, and once those blocks exceed a second threshold they are merged into a single tighter digest, reducing token pressure while preserving semantic content.
Beyond auto-compression, the plugin ships two recall tools: recall retrieves original messages by index range including image attachments, and recall-semantic runs a local embedding model to perform semantic search across all full messages so content buried inside summaries can still be surfaced. Abstract parsing uses a tag-anchored extraction pipeline with a fuzzy-rebuild fallback, and when core services misbehave the compressor degrades gracefully, reporting a single warning event rendered as an expandable row in the browser client without blocking the session.
If you rely on DSH for multi-turn agent workflows or long-chain reasoning and want tighter context management than the built-in compaction-basic while keeping the ability to trace back to original messages at any time, this plugin is a strong fit. Even with auto-compression disabled, the recall and recall-semantic tools remain fully functional, making it suitable for everything from solo long sessions to multi-agent coordination pipelines.
Use Cases
- Automatically compress long session history to control token usage
- Inspect original messages by index even after compression
- Search all full messages semantically using a local embedding model
Best For
- DSH users who need fine-grained context management in multi-turn agents
- Developers handling long-chain reasoning while retaining recall of original messages
- Teams that want more control over summarization pacing than default compaction
Related Plugins

Memory layer for coding agents that indexes local session history and auto-recalls relevant context before edits, commands, and failures, with no manual search needed.
Traceable, searchable cross-session memory for AI agents that turns conversation knowledge into a typed knowledge graph and recalls relevant subgraphs instead of replaying full history, natively integrated with DeepSeek Harness.
Gives DSH AI cross-session long-term memory, to-do and skill management, plus multi-session orchestration, external AI delegation, and an infinite canvas that grows with you.
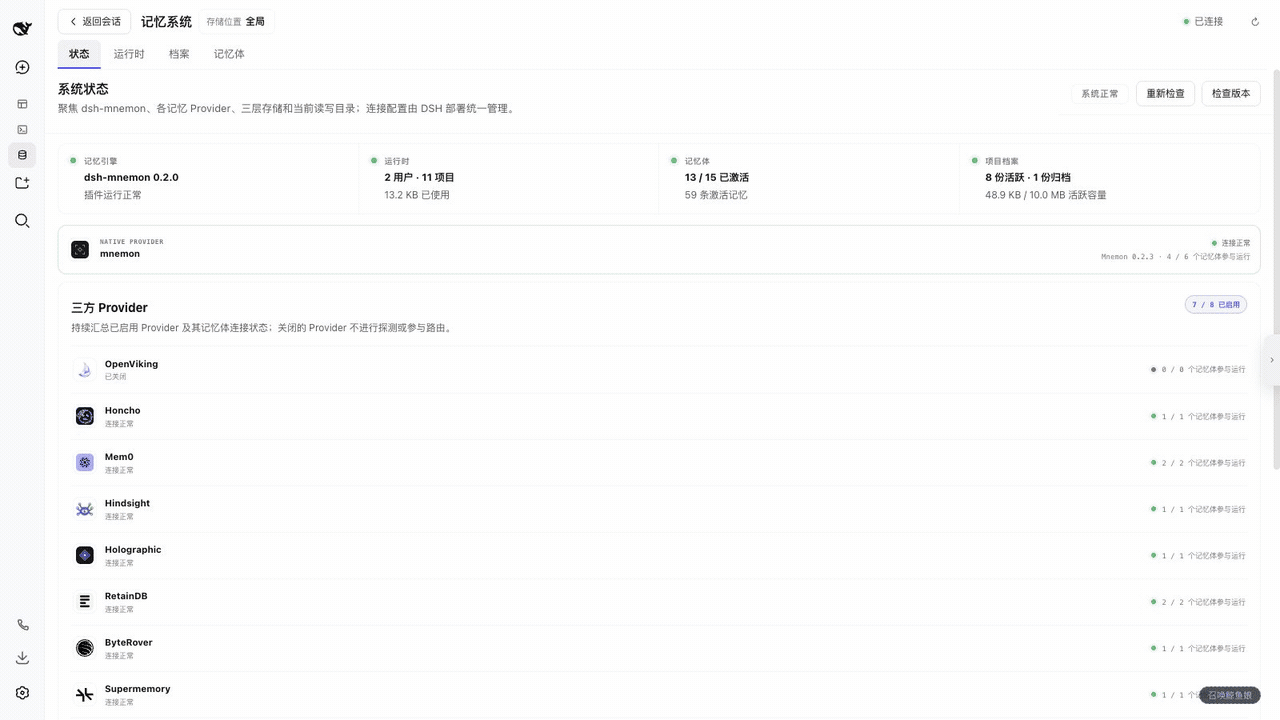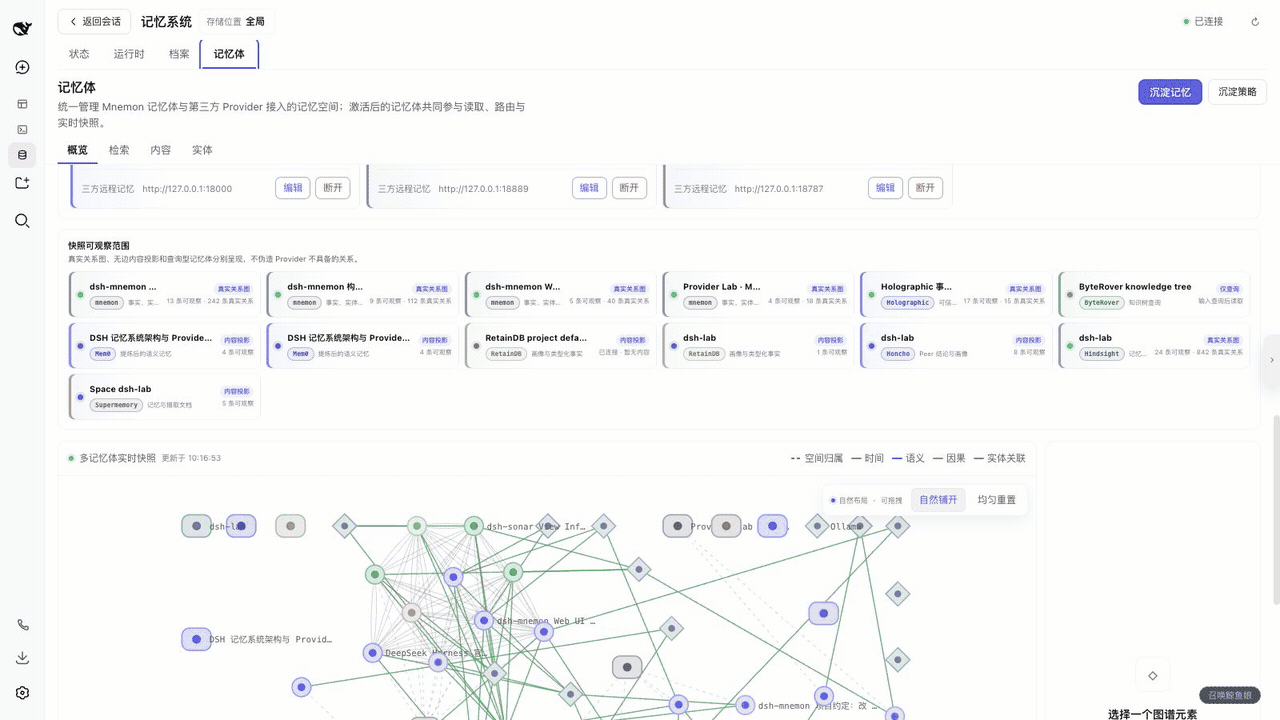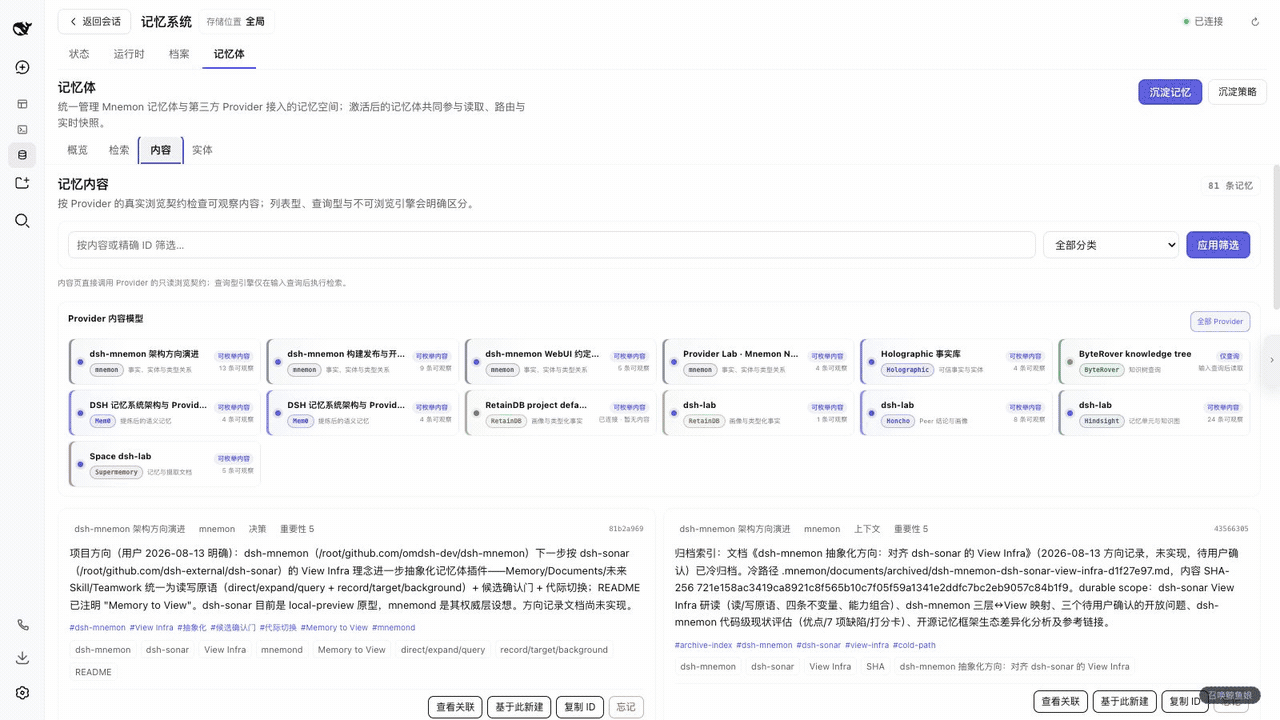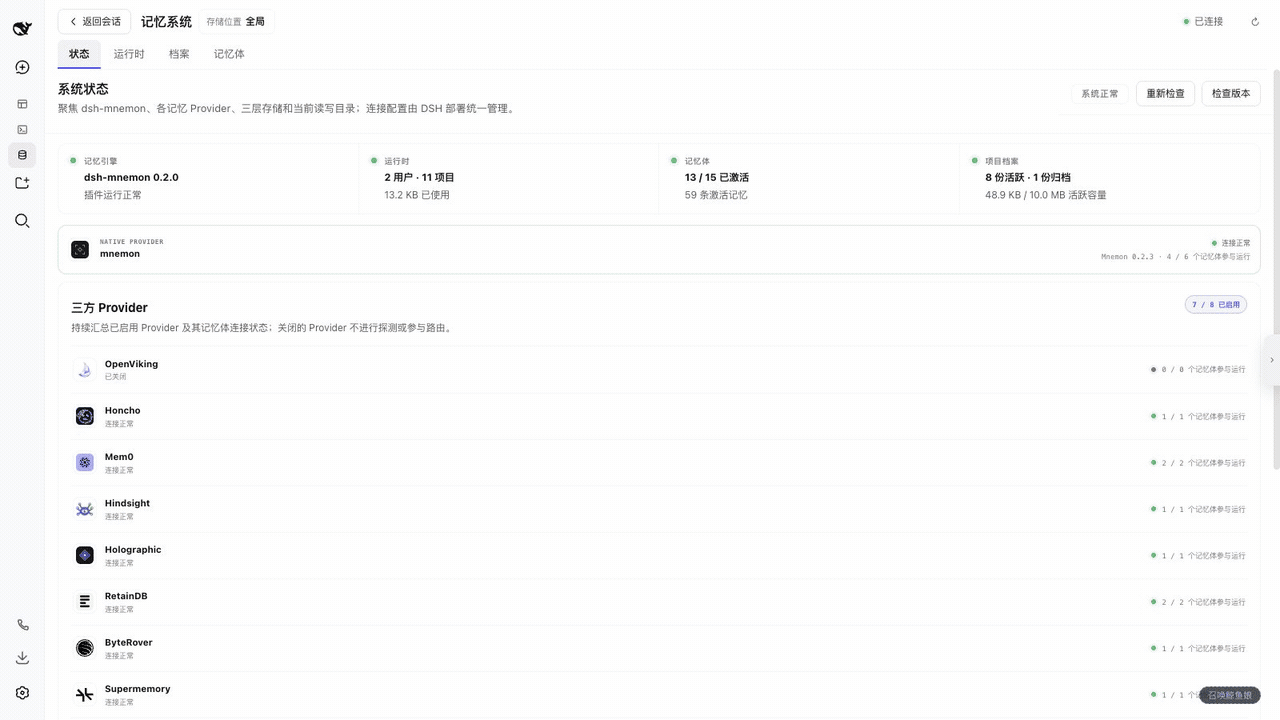
dsh-mnemon is a three-tier, pluggable, Agent-driven memory system for DeepSeek Harness, combining Runtime memory, Project Documents, and replaceable Memory Spaces with nine long-term providers.