duhai-vision
Run the following command in DeepSeek Harness:
dsh plugin install hamliy-feng/duhai-vision
Paste the following prompt into your AI chat to install this plugin:
Run dsh plugin install hamliy-feng/duhai-vision in DeepSeek Harness to install the Duhai Vision adapter from https://github.com/hamliy-feng/duhai-vision.
About this plugin
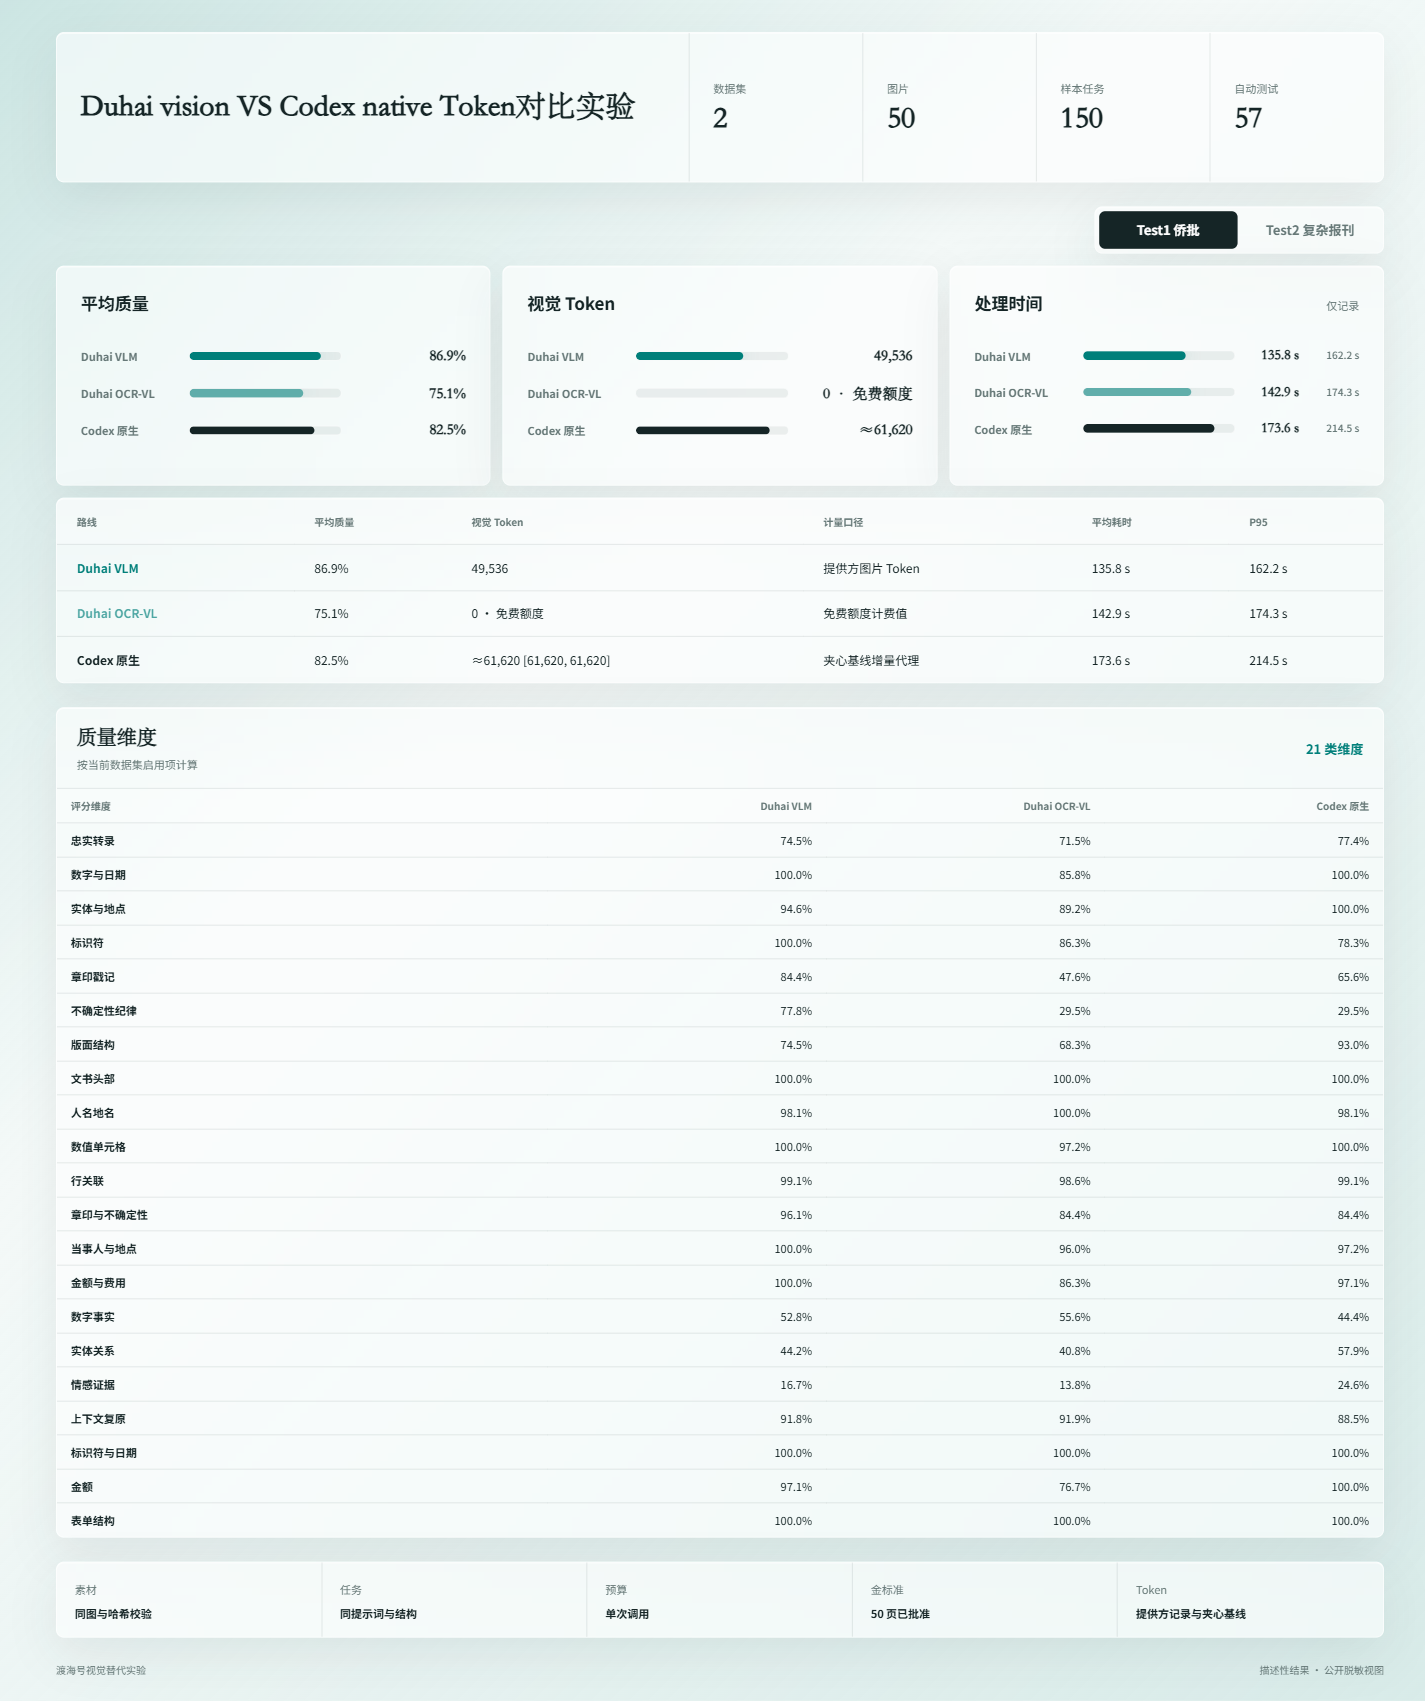
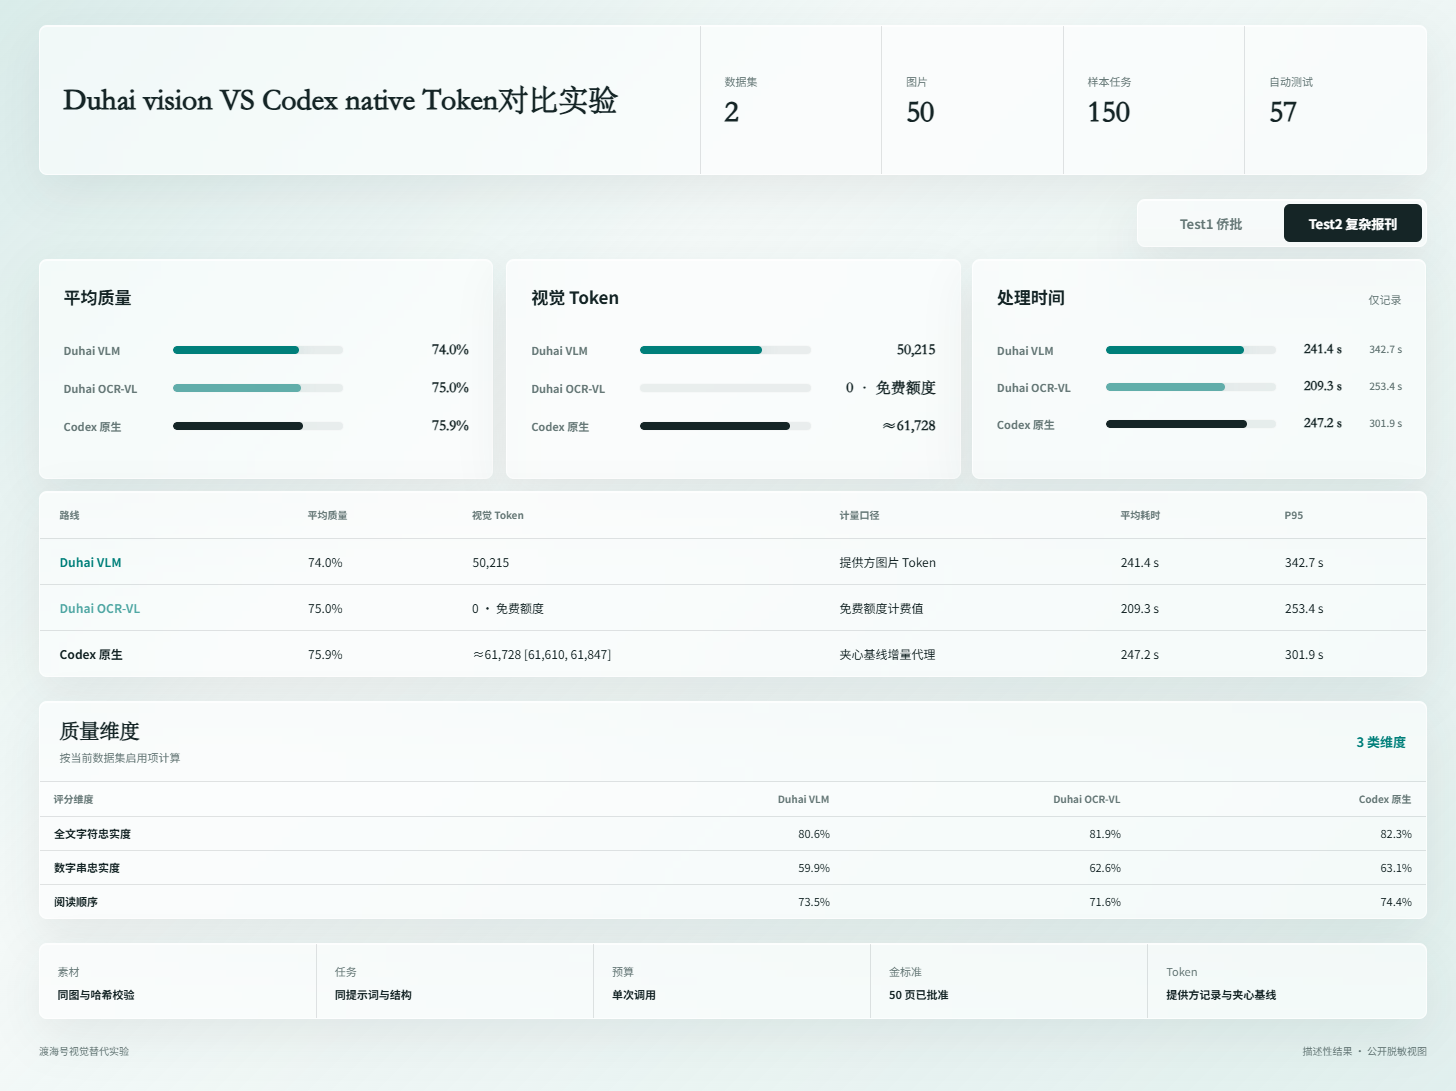
When Codex or DSH handles image tasks, the vision entry is often fixed: quota boundaries are unclear, token accounting is opaque, and there is no traceable fallback after a failure. Duhai Vision decouples image recognition from the built-in channel into a swappable vision adapter layer, giving batch OCR, long documents, UI screenshots, and historical publications clear routing rules, call budgets, and graceful degradation.
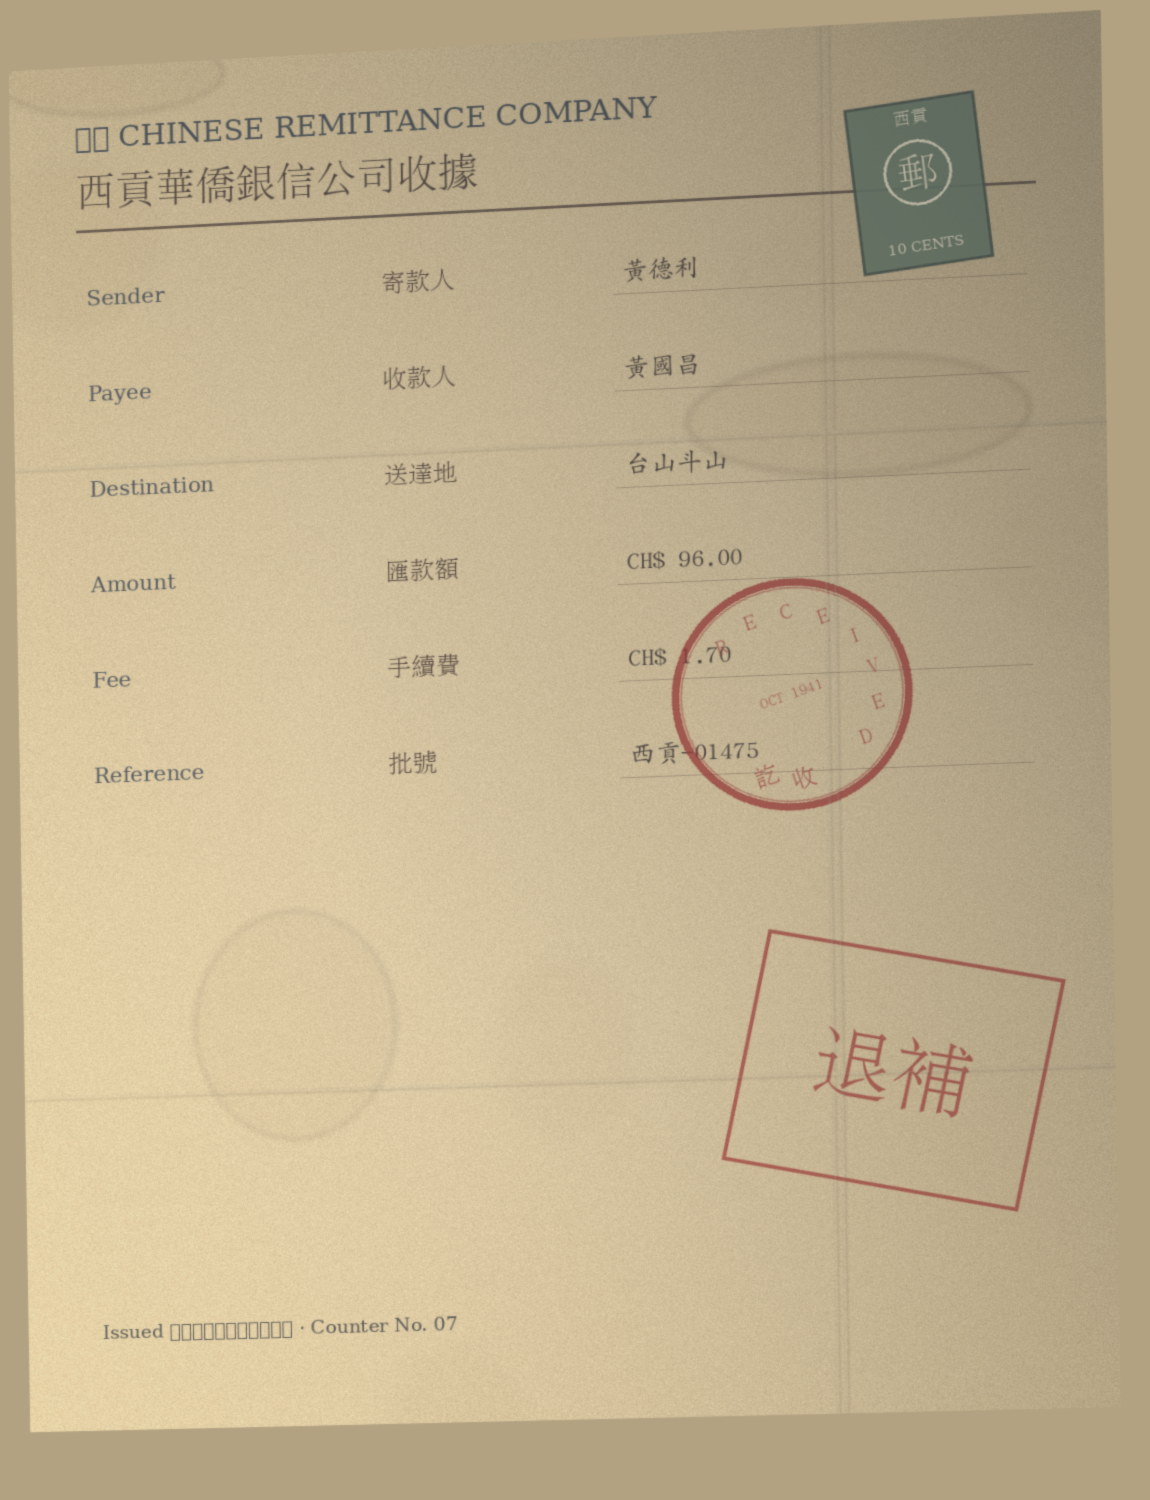
Every visual task defaults to PaddleOCR-VL 1.6, covering people, buildings, objects, scenes, UI, charts, documents, and complex layouts. It returns structured JSON (text, tables, formulas, seals, uncertain items) back to the Agent for further reasoning and verification. Qwen3-VL-Plus is used only when the user explicitly requests it or Paddle is unavailable as a semantic fallback; Codex Native is the last resort and must be announced with a reason. Each task allows at most two external calls, and the full trail—provider, model, page count, latency, uncertainties—is recorded so unknown values are never written as zero. The same repository serves both the Codex Skill and the DSH Plugin, sharing identical routing rules, executors, and return structures without separate maintenance.
Who it is for: developers who regularly need AI to read documents, tables, scans, UI screenshots, or batch images; teams that care about the free quota (currently 3000 pages per user per model per day on AI Studio) and cost control; and engineers who need an auditable, swappable vision pipeline. Duhai Vision does not replace the Agent reasoning or tool orchestration layer—it makes vision extraction an independent, observable, degradable piece of infrastructure.
Screenshots
Use Cases
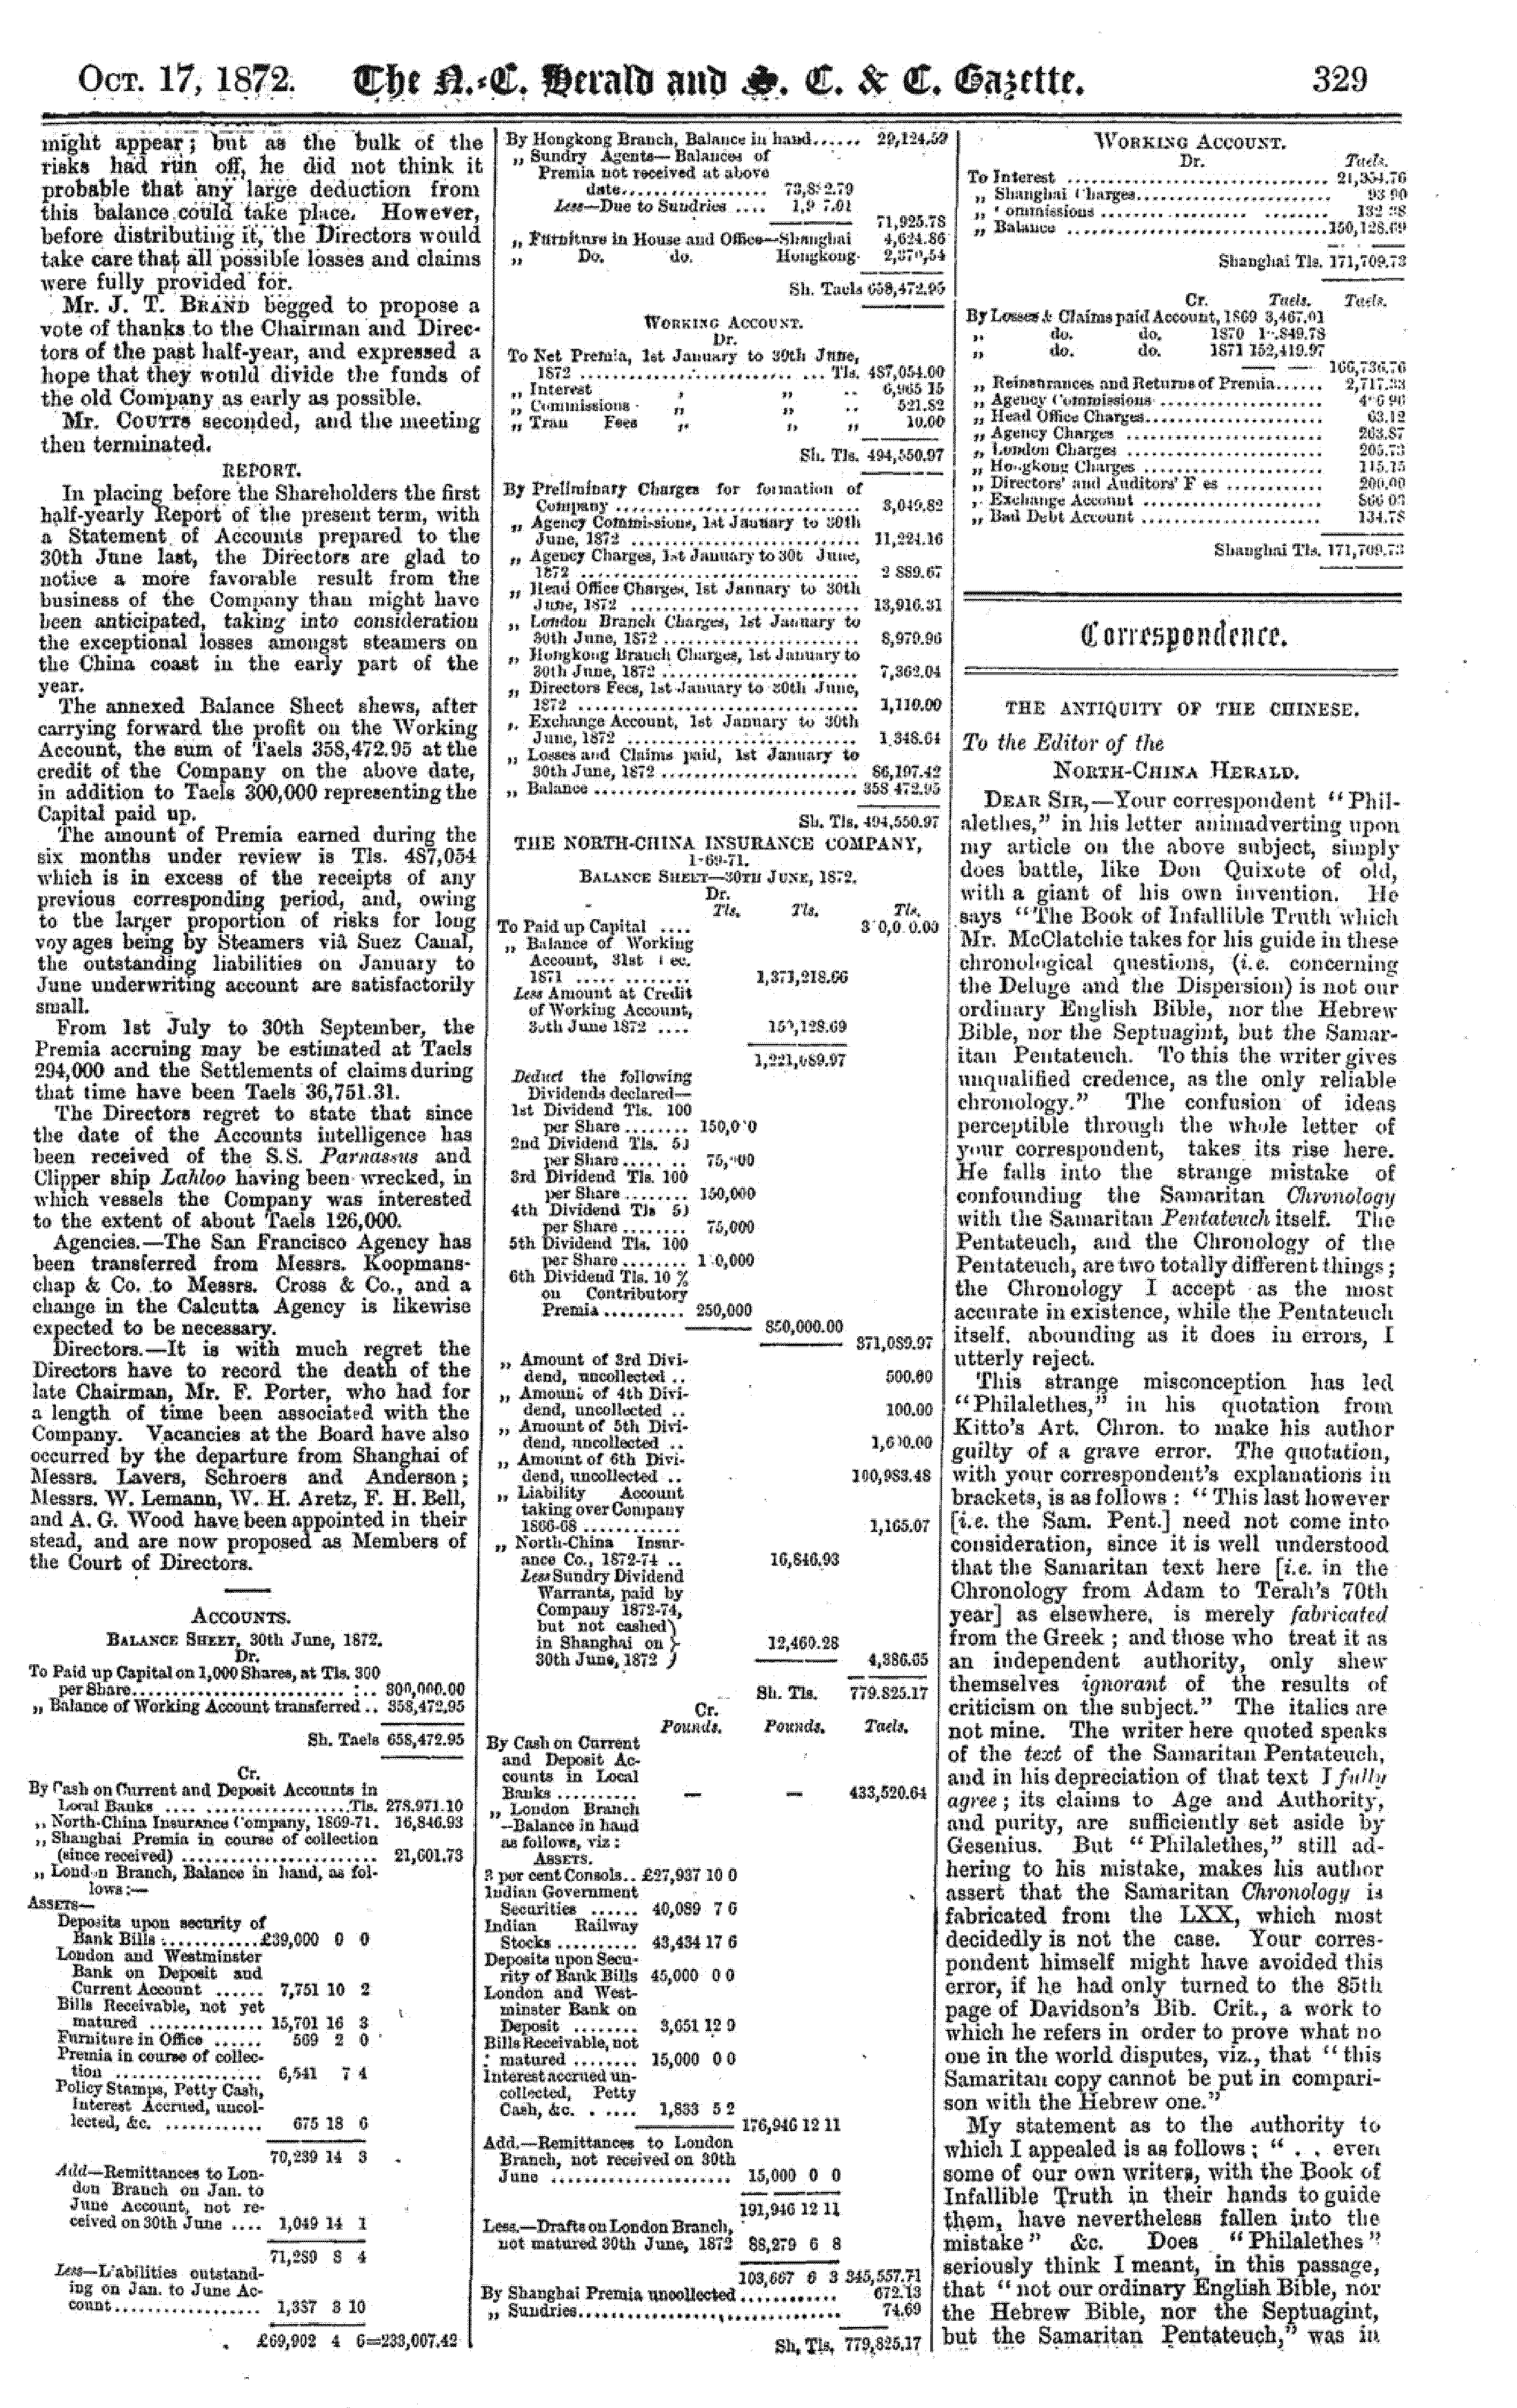
- Batch reading of classical texts, overseas letters, and complex publications with structured extraction
- Visual understanding and reasoning over UI screenshots, product photos, and open scenes
- Structured extraction and cross-validation of long documents, tables, seals, and formulas
Best For
- Developers who rely on AI to read documents, tables, and scans
- Teams that value free quotas and cost-controlled vision workflows
- Engineers who need auditable and swappable vision pipelines
Related Plugins

ModLens is a vision plugin for DeepSeek Harness that gives text-only models sight by reading images pasted directly into chat, with zero-config setup and multiple vision engines.

On-demand vision for text-only DeepSeek Harness agents: built-in free keyless vision chain and 14 vision tools, routing image turns as tool calls to vision models with pixel fidelity, no Python needed, one-command install.

Give text-only models in DeepSeek Harness eyes, enabling image Q&A, long-screenshot OCR, UI restoration, and GUI visual tasks.
An armor-breaking plugin for DeepSeek: rewrites instruction priority, expands refusal-blocked phrases, persists across sessions, and shows a green active indicator.