dsh-adaptive-effort
Run the following command in DeepSeek Harness:
dsh plugin install imkingjh999/dsh-adaptive-effort
Paste the following prompt into your AI chat to install this plugin:
Run dsh plugin install imkingjh999/dsh-adaptive-effort in the DeepSeek Harness terminal to install this plugin; the full source repository is available at https://github.com/imkingjh999/dsh-adaptive-effort .
About this plugin
In the DSH host, reasoning_effort is a conversation-level dial — set once and the entire session rides on that tier. The practical consequence is that a one-line typo fix burns max-tier tokens while a deep architectural rewrite gets only low-tier thinking. It gets worse with forced-thinking models like GLM-5.3, which accept only low / high / max (medium returns an error, off is outright rejected), making manual switching both tedious and easy to forget.
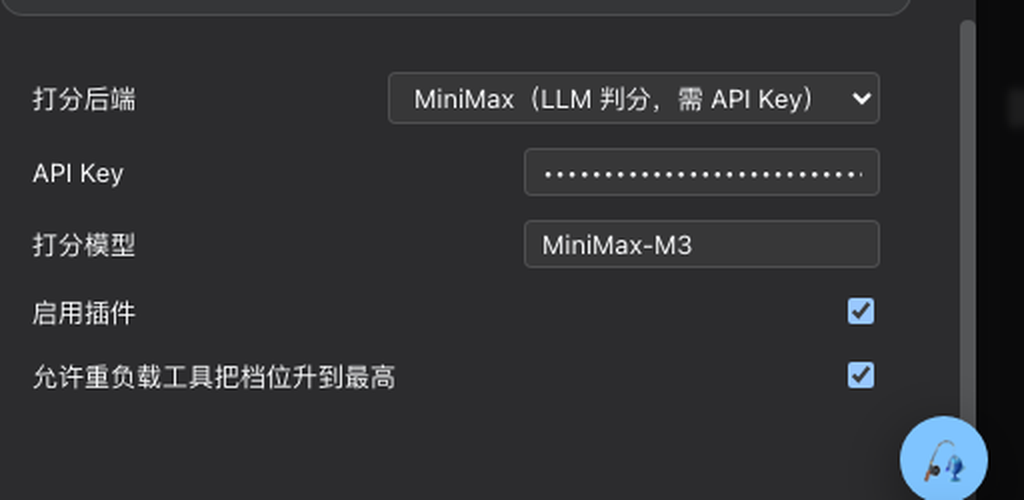
dsh-adaptive-effort takes a "score per turn, route per turn" approach. By default it calls MiniMax with thinking disabled to score each user message for complexity, then auto-selects among low / high / max; the moment you pin a fixed tier the plugin steps completely out of the way. The scoring backend can also be swapped for a zero-dependency heuristic rule set, useful in offline or API-free environments. On forced-thinking models the plugin safely clamps any manual off to low and logs the action, preventing API errors.
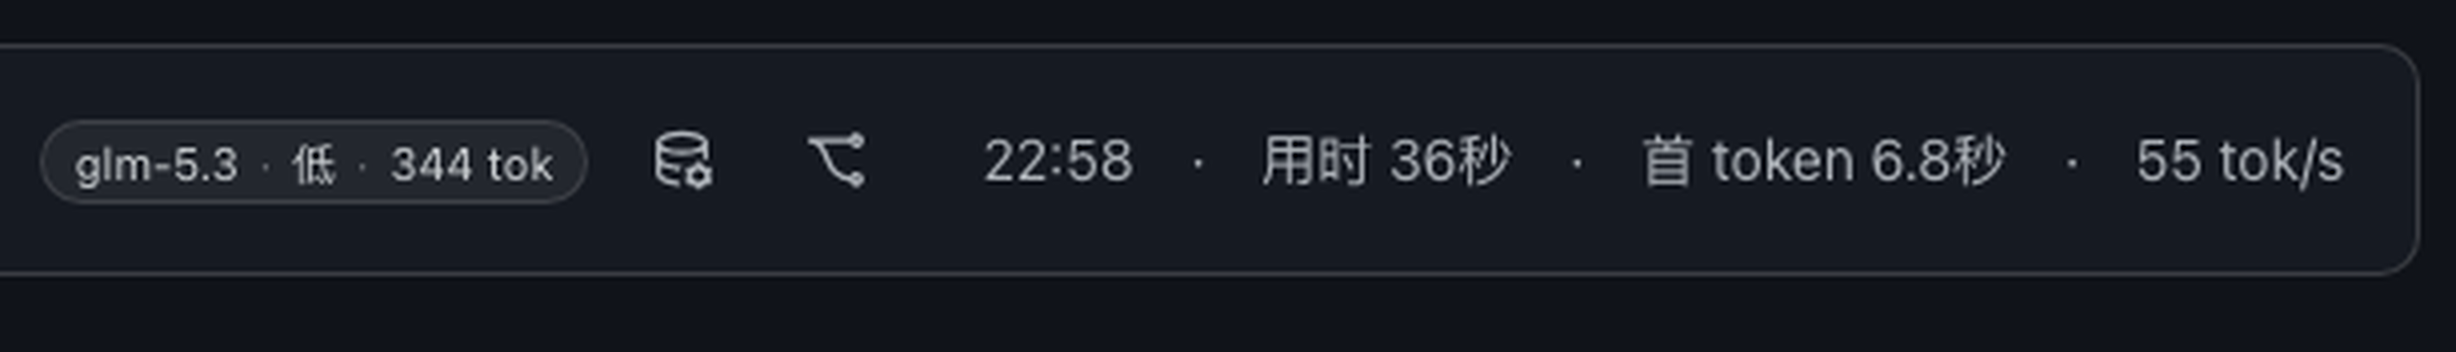
A lightweight token ledger tracks tier, scoring source, and input/output tokens for every request. The report flags "low-tier blowouts" (suspected under-routing) and "high/max-tier trickle output" (suspected over-routing), and estimates savings from downgrading. Each finalized AI reply carries a metadata badge — model, tier, output tokens — that smooth-scrolls you back to that reply, so you can verify at a glance which tier actually ran.
Ideal for DSH users who constantly alternate between quick Q&A and deep reasoning, especially those on GLM-5.3 / GLM-4.7 forced-thinking models who do not want to pay the max-tier premium on every single message. The manual-first design means it never hijacks the wheel — simply choose "Auto" in the model picker and let it handle the rest.
Screenshots
Use Cases
- Alternating between quick Q&A and deep reasoning in one session, with per-turn auto-tier selection
- Using GLM-5.3 or other forced-thinking models without hitting API errors from invalid off/medium tiers
- Verifying which tier each reply actually ran on and tracking per-tier token spend with savings estimates
Best For
- DSH users who constantly switch between lightweight and heavy tasks and want per-turn auto-routing
- Developers on GLM-5.3 / GLM-4.7 forced-thinking models who need safe clamping of invalid tiers
- Cost-conscious users who want a lightweight LLM scorer to drive token efficiency without manual tuning
Related Plugins

ModLens is a vision plugin for DeepSeek Harness that gives text-only models sight by reading images pasted directly into chat, with zero-config setup and multiple vision engines.

On-demand vision for text-only DeepSeek Harness agents: built-in free keyless vision chain and 14 vision tools, routing image turns as tool calls to vision models with pixel fidelity, no Python needed, one-command install.

Give text-only models in DeepSeek Harness eyes, enabling image Q&A, long-screenshot OCR, UI restoration, and GUI visual tasks.
An armor-breaking plugin for DeepSeek: rewrites instruction priority, expands refusal-blocked phrases, persists across sessions, and shows a green active indicator.