auto-vision
Run the following command in DeepSeek Harness:
dsh plugin install h-k-c/auto-vision
Paste the following prompt into your AI chat to install this plugin:
Run dsh plugin install h-k-c/auto-vision to install; source code: https://github.com/h-k-c/auto-vision
About this plugin
Pasting an image into a DeepSeek Harness chat and getting an error—while the image itself never renders—breaks the workflow in a way that is hard to ignore. auto-vision fixes exactly that: images now display normally in the chat window and the conversation continues without interruption.
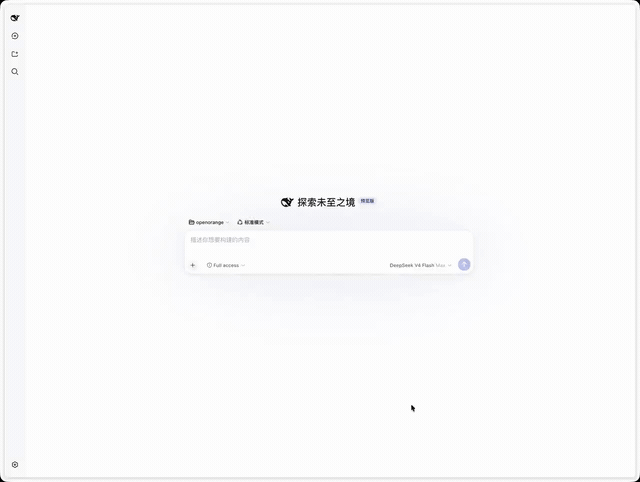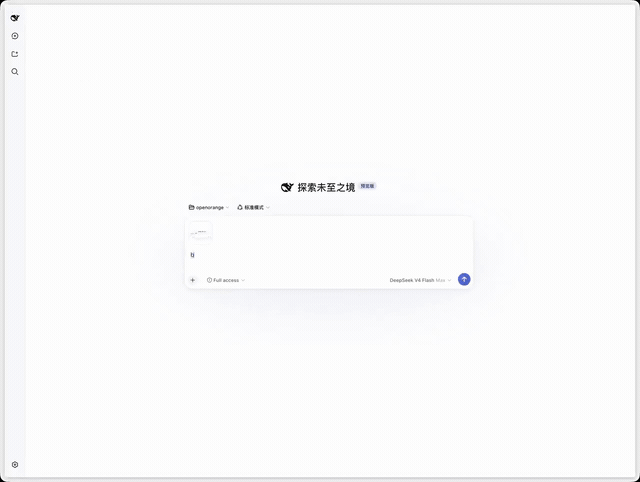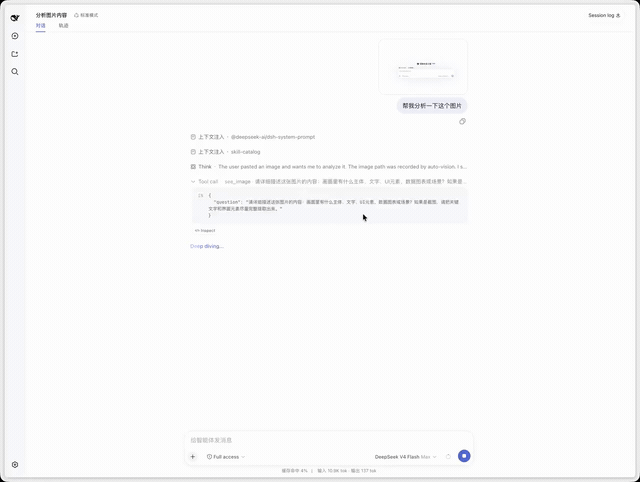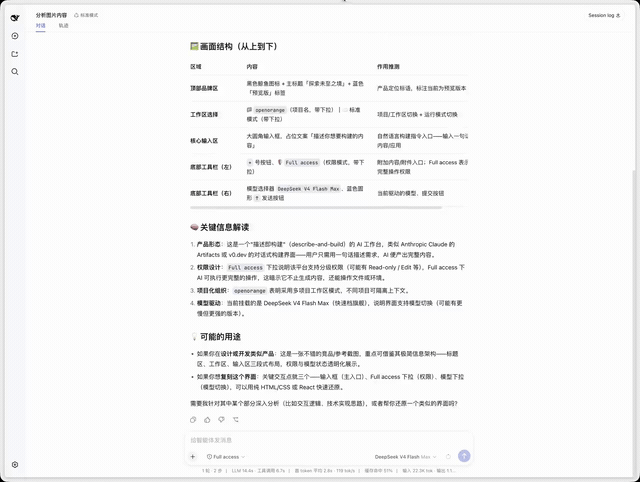
The more interesting part is the transparency. The model decides on its own whether the current turn needs visual reading. When it does, it calls a vision model, extracts the content, and folds the result back into text reasoning—no manual trigger required on your end. Vision-model choice is flexible out of the box: it ships with ModelScope Qwen3-VL free tier by default, can switch to Zhipu GLM-4V-Flash at zero cost, or point at any OpenAI-compatible endpoint you run yourself (local Ollama, a self-hosted inference service, etc.) by supplying a key, URL, and model name.
It is built for users who regularly paste screenshots, design mockups, or product photos into the DSH web interface and want the model to reason over them. If you prefer free vision calls over per-request API fees, or you keep your image data behind a private model endpoint, this is a natural fit.
Screenshots

Use Cases
- Paste screenshots or mockups into the DSH chat window; images render and the model reads them automatically
- Use Zhipu or ModelScope free-tier vision models to read images at zero cost
- Wire up a local Ollama or self-hosted vision service via an OpenAI-compatible endpoint to keep data on-site
Best For
- DSH web users who paste images often and want error-free conversations
- Independent developers who want free vision calls and tight cost control
- SME or research teams with private vision models that need on-premises data flow
Related Plugins

ModLens is a vision plugin for DeepSeek Harness that gives text-only models sight by reading images pasted directly into chat, with zero-config setup and multiple vision engines.

On-demand vision for text-only DeepSeek Harness agents: built-in free keyless vision chain and 14 vision tools, routing image turns as tool calls to vision models with pixel fidelity, no Python needed, one-command install.

Give text-only models in DeepSeek Harness eyes, enabling image Q&A, long-screenshot OCR, UI restoration, and GUI visual tasks.
An armor-breaking plugin for DeepSeek: rewrites instruction priority, expands refusal-blocked phrases, persists across sessions, and shows a green active indicator.