dsh-conversation-cost
Run the following command in DeepSeek Harness:
dsh plugin install WinnieJQ/dsh-conversation-cost
Paste the following prompt into your AI chat to install this plugin:
Run dsh plugin install WinnieJQ/dsh-conversation-cost in your DeepSeek Harness terminal (source: https://github.com/WinnieJQ/dsh-conversation-cost), then restart dsh web to activate the badge.
About this plugin
Running long multi-turn conversations in DeepSeek Harness raises a deceptively simple question: how much did this session actually cost? The usual answer was to pause your work, open the DeepSeek billing page, and dig through line-item charges. dsh-conversation-cost removes that friction entirely—a cost badge now sits right beside the conversation title in the web UI, and hovering over it unfolds a step-by-step breakdown by model, token type, and peak/off-peak window, all without leaving the page.
Under the hood the plugin keeps things precise yet lightweight. Every LLM step is folded into a per-step usage record (input, cache-hit, and output tokens), linked to the model that actually executed it, and priced against the official rate card split by peak and off-peak windows. The badge and the hover card both show the amount in CNY and USD, with the exchange rate and per-model prices fully configurable. There are zero runtime dependencies and no build step: the host side is pure ESM and the browser side uses a hand-written module factory, so it drops in and starts updating the badge the moment each step completes.
If you run heavy daily workloads through Harness, want to keep a running eye on your API spend, or share a team quota and need transparent per-session accounting, this lightweight badge is the simplest cost dashboard you can add to your workflow.
Use Cases
- Check cumulative session spend at a glance during long multi-turn web conversations
- Quickly identify per-session cost when a team shares an API quota
- Compare actual spend across models and peak/off-peak windows to inform model choice
Best For
- Developers who spend most of their day in the DeepSeek Harness web UI
- Engineering teams that need per-session cost visibility to stay within API budgets
- AI application developers who swap models and context lengths and care about token-level spend
Related Plugins
A service-oriented sidebar framework for DSH, offering a full workbench with file explorer, embedded browser, real terminal, Git panel, and extensible plugin services.
A beautiful, practical Claude Code-style TUI plugin with pixel whale top bar, flowing glow title, real-time status line, streaming thought expansion, time rewind, context progress bar and TPS gauge — zero core changes.
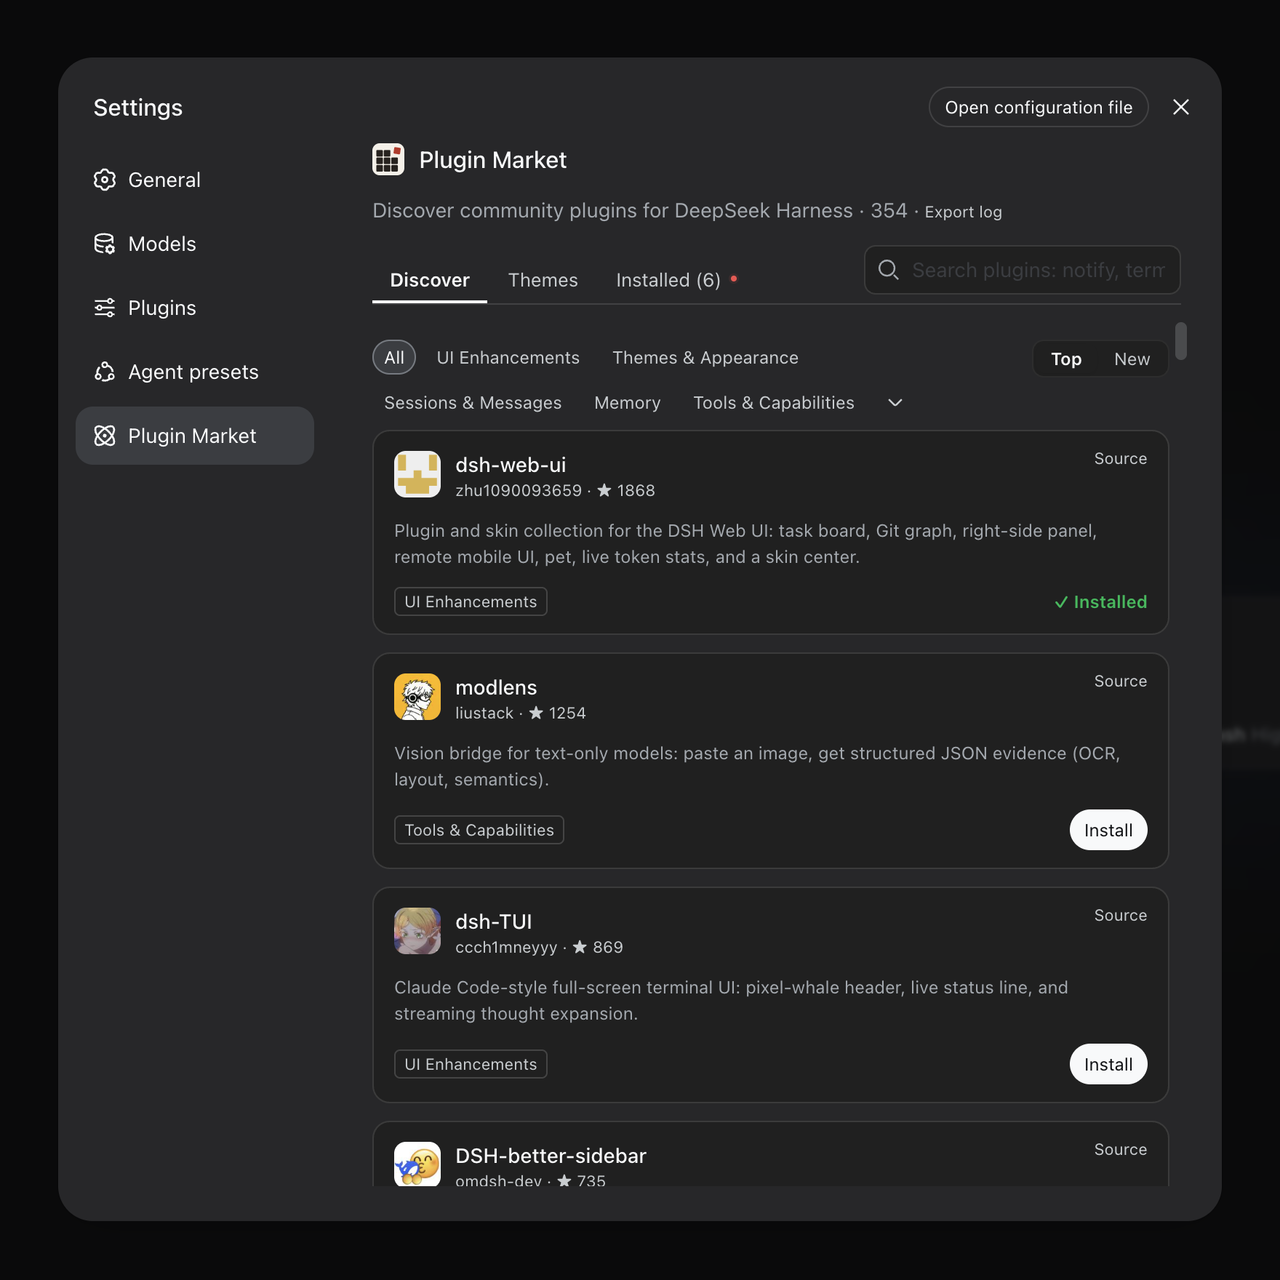
The plugin market for DeepSeek Harness: browse/search/one-click install community plugins and themes, with updates, backup/restore, hot disable, diagnostics, and AI fix.
A persistent whale widget on the DSH web UI that shows DeepSeek balance, today's usage, and per-turn cost, with drag-and-snap and sound effects.