
GLM-4.6
About this model
GLM-4.6

👋 Join our Discord community.
📖 Check out the GLM-4.6 technical blog, technical report(GLM-4.5), and Zhipu AI technical documentation.
📍 Use GLM-4.6 API services on Z.ai API Platform.
👉 One click to GLM-4.6.
Model Introduction
Compared with GLM-4.5, GLM-4.6 brings several key improvements:
- Longer context window: The context window has been expanded from 128K to 200K tokens, enabling the model to handle more complex agentic tasks.
- Superior coding performance: The model achieves higher scores on code benchmarks and demonstrates better real-world performance in applications such as Claude Code、Cline、Roo Code and Kilo Code, including improvements in generating visually polished front-end pages.
- Advanced reasoning: GLM-4.6 shows a clear improvement in reasoning performance and supports tool use during inference, leading to stronger overall capability.
- More capable agents: GLM-4.6 exhibits stronger performance in tool using and search-based agents, and integrates more effectively within agent frameworks.
- Refined writing: Better aligns with human preferences in style and readability, and performs more naturally in role-playing scenarios.
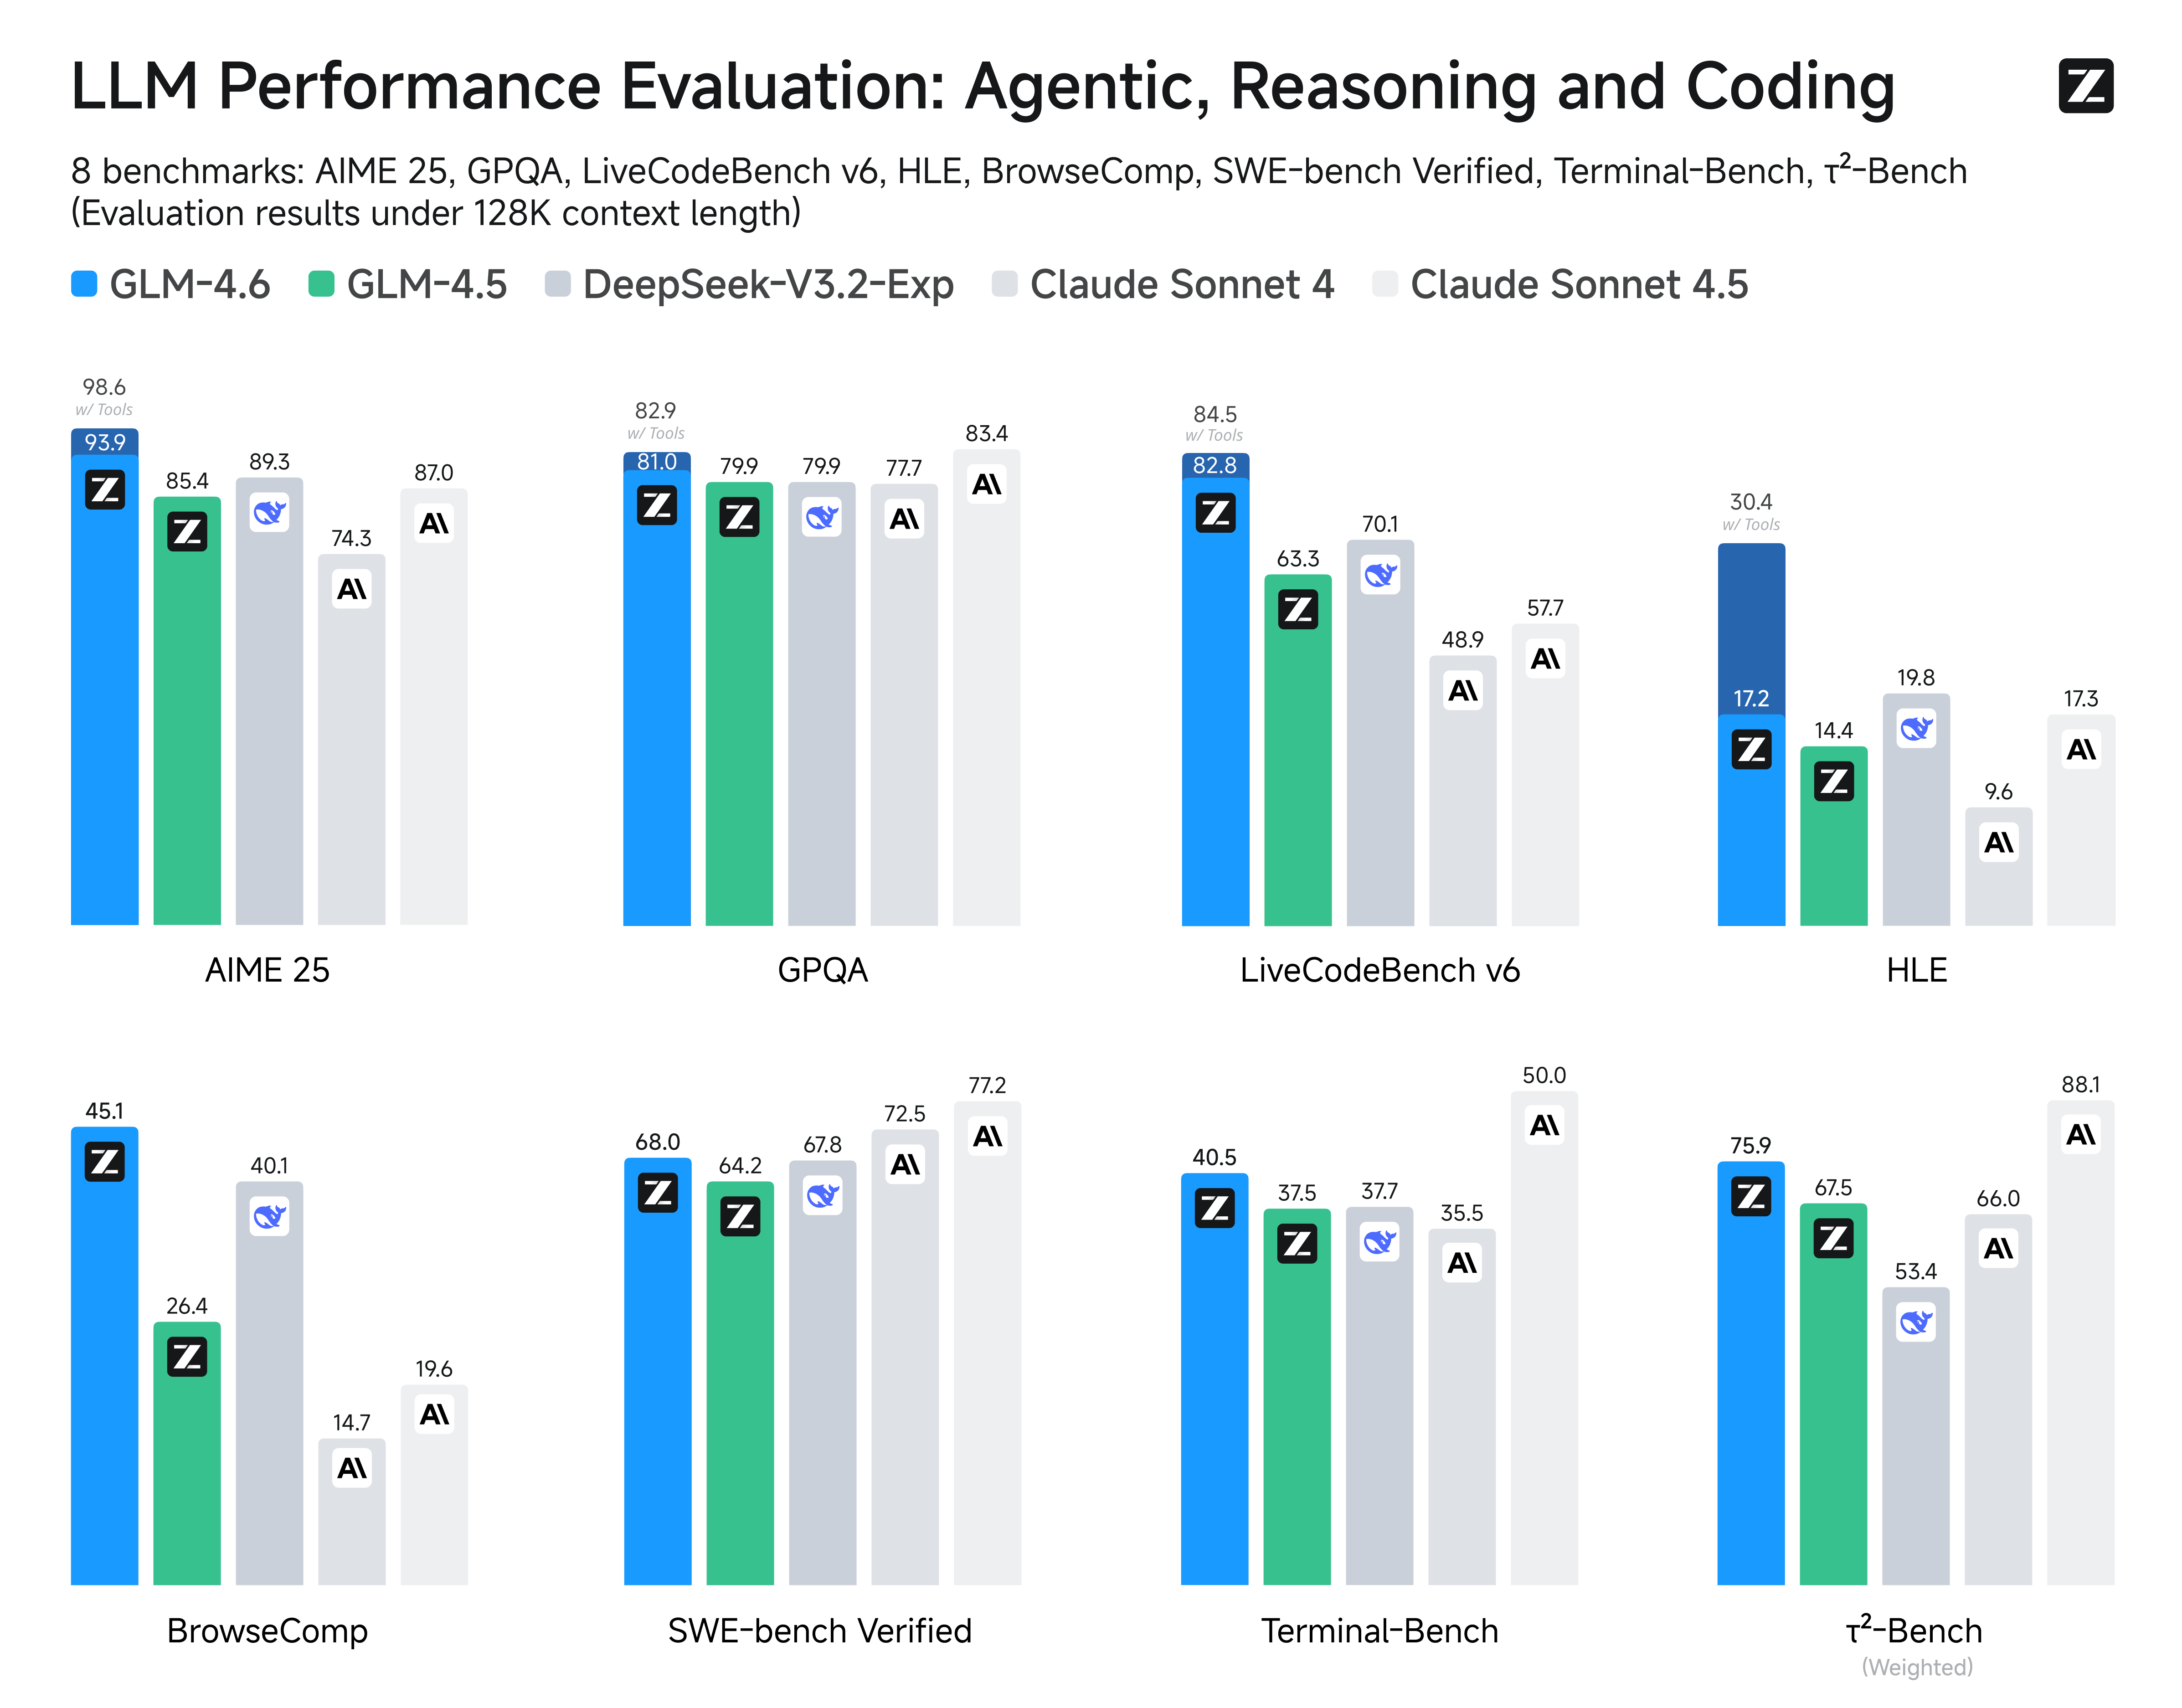
We evaluated GLM-4.6 across eight public benchmarks covering agents, reasoning, and coding. Results show clear gains over GLM-4.5, with GLM-4.6 also holding competitive advantages over leading domestic and international models such as DeepSeek-V3.1-Terminus and Claude Sonnet 4.
Inference
Both GLM-4.5 and GLM-4.6 use the same inference method.
you can check our github for more detail.
Recommended Evaluation Parameters
For general evaluations, we recommend using a sampling temperature of 1.0.
For code-related evaluation tasks (such as LCB), it is further recommended to set:
top_p = 0.95top_k = 40
Evaluation
Benchmark Scores
Technical Specs
- Architecture: transformers
- Context Window: 204,800 tokens
- Input Modalities: text
Hardware Requirements
- API-only (no local hardware needed)
Pricing
| Input | Output | Currency |
|---|---|---|
| 0.43 / 1M tokens | 1.75 / 1M tokens | USD |
Related Models
More Open Source →
Description: The NVIDIA DeepSeek-V4-Pro-NVFP4 model is the quantized version of the DeepSeek-V4-Pro model, which is a Mixture-of-Experts (MoE) language model with 1.6 trillion total parameters and 49 billion activated parameters. For more information, please check here. The NVIDI…
Description: The NVIDIA GLM-5.2 NVFP4 model is the quantized version of ZAI’s GLM-5.2 model, which is an auto-regressive language model that uses an optimized transformer architecture. GLM-5.2 is a Mixture-of-Experts (MoE) model for reasoning and coding that uses sparse attention…
👋 Join our WeChat or Discord community. 📖 Check out the GLM-5.2 blog and GLM-5 Technical report . 📍 Use GLM-5.2 API services on Z.ai API Platform. 🔜 Try GLM-5.2 here .
👋 Join our WeChat or Discord community. 📖 Check out the GLM-5.2 blog and GLM-5 Technical report . 📍 Use GLM-5.2 API services on Z.ai API Platform. 🔜 Try GLM-5.2 here .