
Yarn-Solar-10b-32k
About this model
Model Card: Yarn-Solar-10b-32k
Model Description
Yarn-Solar-10b-32k is a state-of-the-art language model for long context, further pretrained on two billion long context tokens using the YaRN extension method. It is an extension of SOLAR-10.7B-v1.0 and supports a 32k token context window.
To use, pass trust_remote_code=True when loading the model, for example
model = AutoModelForCausalLM.from_pretrained("NousResearch/Yarn-Solar-10b-32k",
  attn_implementation="flash_attention_2",
  torch_dtype=torch.bfloat16,
  device_map="auto",
  trust_remote_code=True)
In addition you will need to use the latest version of transformers
pip install git+https://github.com/huggingface/transformers
Benchmarks
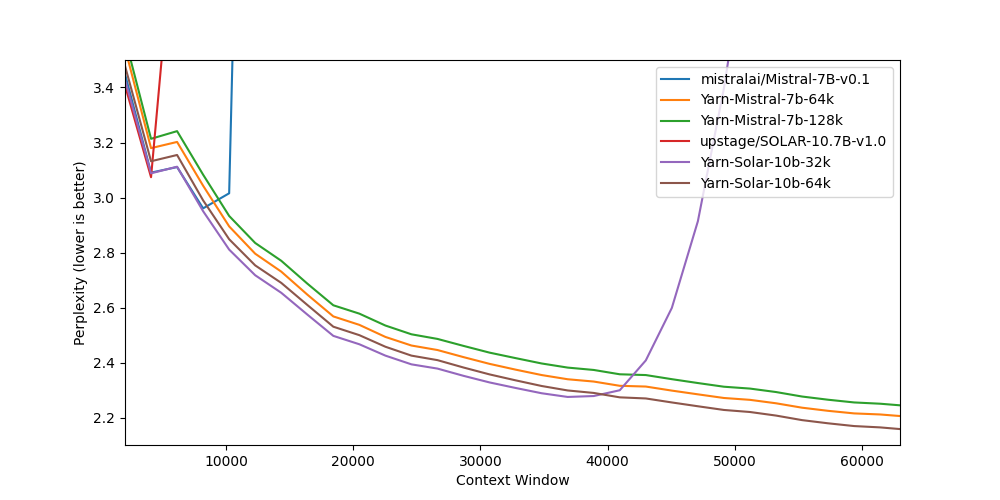
Long context benchmarks:
| Model | Context Window | 4k PPL | 8k PPL | 16k PPL | 32k PPL | 64k PPL |
|---|---|---|---|---|---|---|
| Mistral-7B-v0.1 | 8k | 3.09 | 2.96 | - | - | - |
| Yarn-Mistral-7b-64k | 64k | 3.18 | 3.04 | 2.65 | 2.44 | 2.20 |
| Yarn-Mistral-7b-128k | 128k | 3.21 | 3.08 | 2.68 | 2.47 | 2.24 |
| SOLAR-10.7B-v1.0 | 4k | 3.07 | - | - | - | - |
| Yarn-Solar-10b-32k | 32k | 3.09 | 2.95 | 2.57 | 2.31 | - |
| Yarn-Solar-10b-64k | 64k | 3.13 | 2.99 | 2.61 | 2.34 | 2.15 |
Short context benchmarks showing that quality degradation is minimal:
| Model | Context Window | ARC-c | Hellaswag | MMLU | Truthful QA |
|---|---|---|---|---|---|
| Mistral-7B-v0.1 | 8k | 59.98 | 83.31 | 64.16 | 42.15 |
| Yarn-Mistral-7b-64k | 64k | 59.38 | 81.21 | 61.32 | 42.50 |
| Yarn-Mistral-7b-128k | 128k | 58.87 | 80.58 | 60.64 | 42.46 |
| SOLAR-10.7B-v1.0 | 4k | 61.95 | 84.60 | 65.48 | 45.04 |
| Yarn-Solar-10b-32k | 32k | 59.64 | 83.65 | 64.36 | 44.82 |
| Yarn-Solar-10b-64k | 64k | 59.21 | 83.08 | 63.57 | 45.70 |
Collaborators
- bloc97: Methods, paper and evals
- @theemozilla: Methods, paper, model training, and evals
- @EnricoShippole: Model training
- honglu2875: Paper and evals
The authors would like to thank LAION AI for their support of compute for this model. It was trained on the JUWELS supercomputer.
Benchmark Scores
Technical Specs
- Parameters: 10.7B
- Architecture: Llama-based Transformer with YaRN RoPE scaling
- Context Window: 32,000 tokens
- Input Modalities: text
Hardware Requirements
- VRAM: 24.0 GB
- Compute: Single NVIDIA GPU with 24GB+ VRAM (40GB recommended for full 32k context)
Related Models
More Open Source →
Description: The NVIDIA DeepSeek-V4-Pro-NVFP4 model is the quantized version of the DeepSeek-V4-Pro model, which is a Mixture-of-Experts (MoE) language model with 1.6 trillion total parameters and 49 billion activated parameters. For more information, please check here. The NVIDI…
Description: The NVIDIA GLM-5.2 NVFP4 model is the quantized version of ZAI’s GLM-5.2 model, which is an auto-regressive language model that uses an optimized transformer architecture. GLM-5.2 is a Mixture-of-Experts (MoE) model for reasoning and coding that uses sparse attention…

👋 Join our WeChat or Discord community. 📖 Check out the GLM-5.2 blog and GLM-5 Technical report . 📍 Use GLM-5.2 API services on Z.ai API Platform. 🔜 Try GLM-5.2 here .
👋 Join our WeChat or Discord community. 📖 Check out the GLM-5.2 blog and GLM-5 Technical report . 📍 Use GLM-5.2 API services on Z.ai API Platform. 🔜 Try GLM-5.2 here .