DeepSeek Harness Plugins · Model Inference
Plugins that extend DeepSeek Harness (DSH) with vision, workflows, memory, web tools and more.
An LLM adapter plugin for DeepSeek Harness that accesses WorkBuddy/CodeBuddy models via a local proxy, requiring no API key, and includes a web status widget.
A dsh plugin implementing Best-of-N self-verification to enhance LLM inference quality like frontier models at a fraction of the cost.
This plugin provides cancelable auxiliary model calls, durable limits, and provenance-preserving usage for DeepSeek Harness.
A community DeepSeek Harness plugin that exposes DSH Agents via the AG-UI protocol, providing an authenticated HTTP/SSE gateway, thread-to-agent bindings, streamed text and tool events, browser-owned tools, and turn continuation.
Provides a visual interface for DeepSeek Harness to inspect the details and context sources of each AgentLoop model call request.
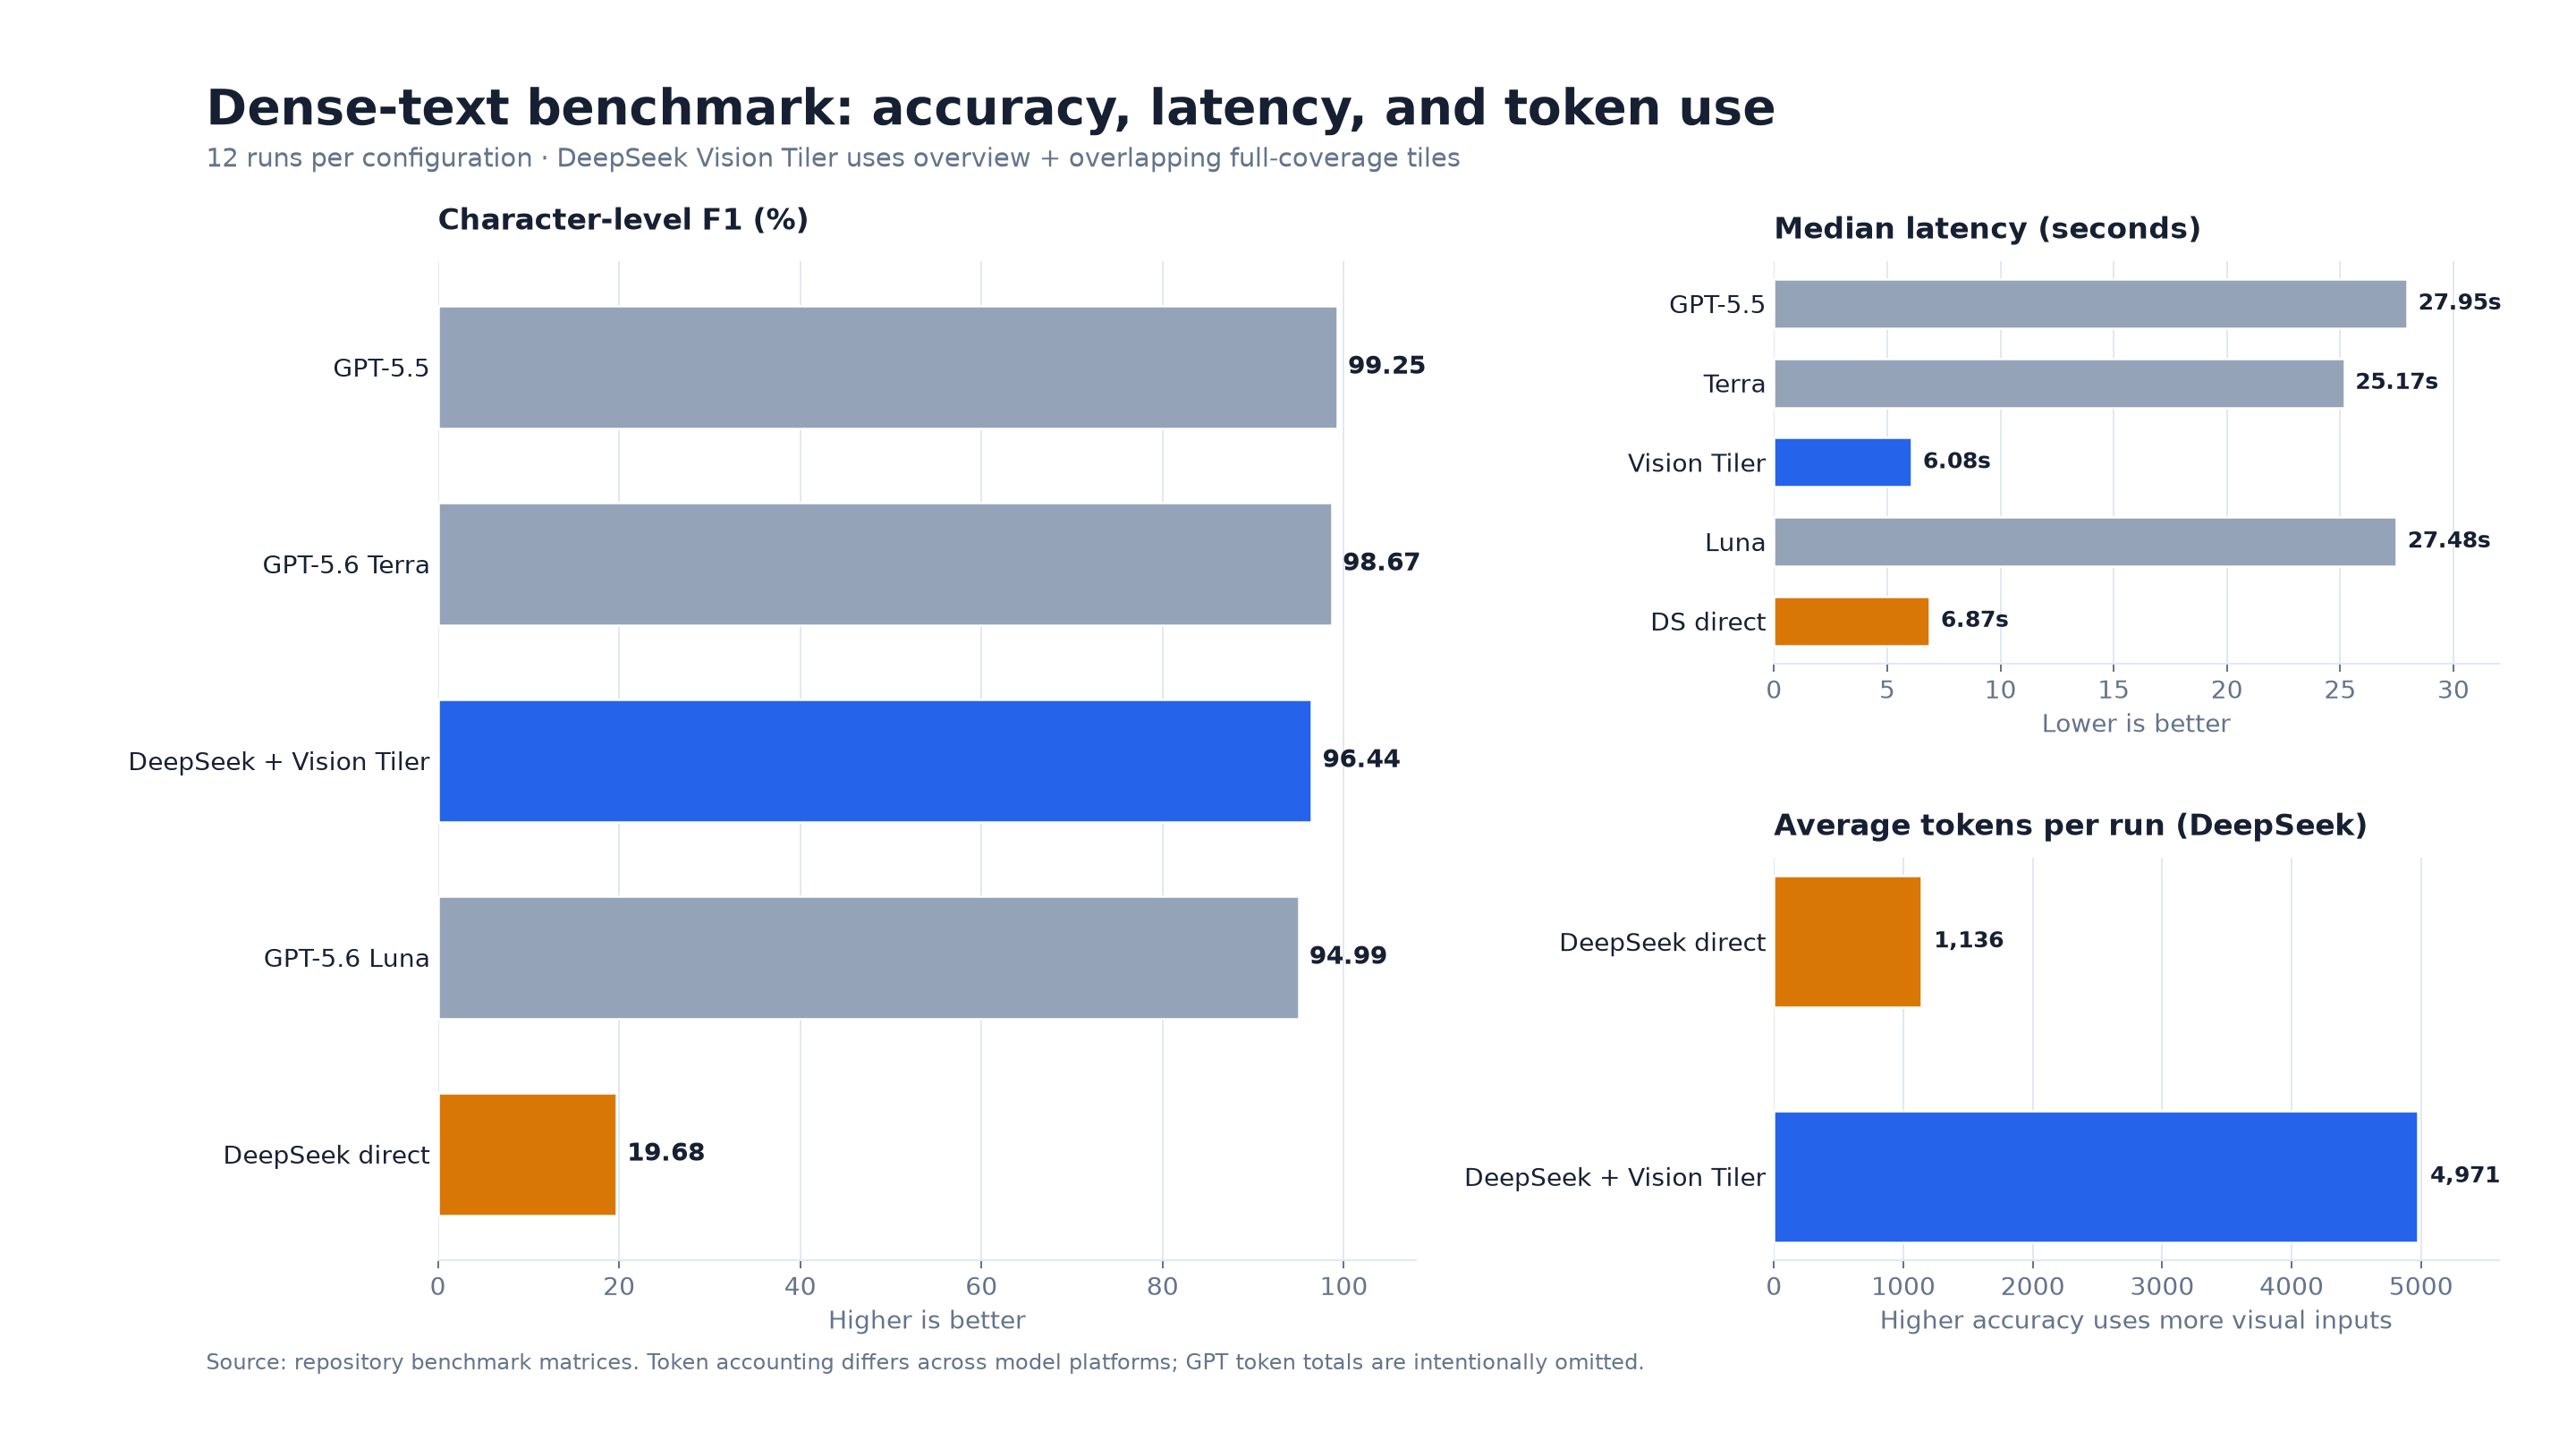
This plugin provides full-coverage image tiling for DeepSeek Harness vision models, enhancing recognition of small text in high-resolution images.
dsh-model-failover is a plugin for DeepSeek Harness that implements a two-level model circuit breaker with failover, automatically routing requests to fallback models when failures occur, without requiring core modifications.
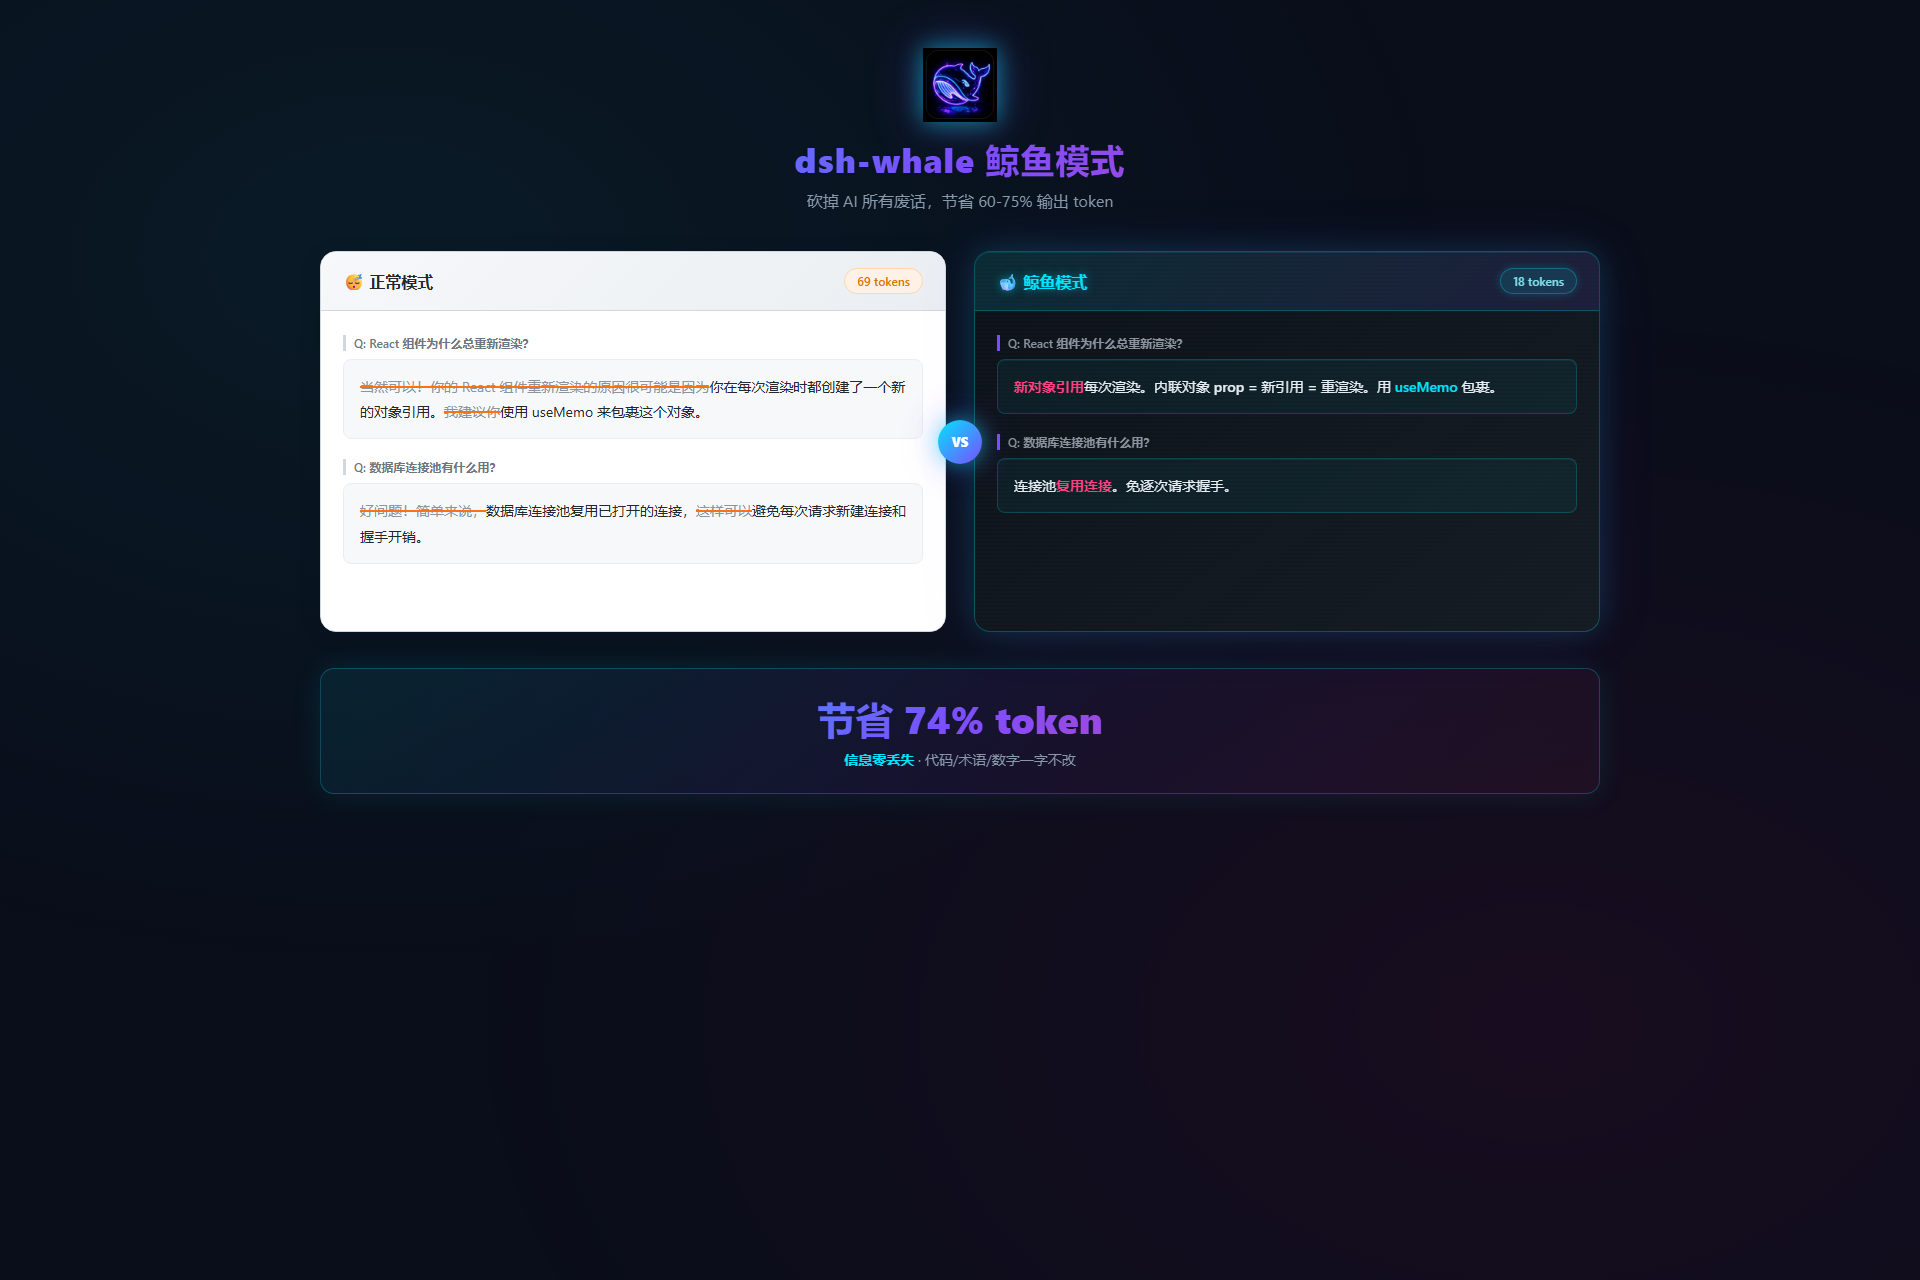
dsh-whale is a slim mode plugin for DeepSeek Harness that trims verbosity from AI responses, offering multiple compression levels to save 60-75% of output tokens while preserving all technical information.
This plugin enables registration and management of various AI models, including language, image, speech, and more, with assisted profile creation and Agent model selection.
dsh-freeroute is a free model aggregation plugin for DeepSeek Harness, providing automatic failover and a local OpenAI-compatible endpoint.
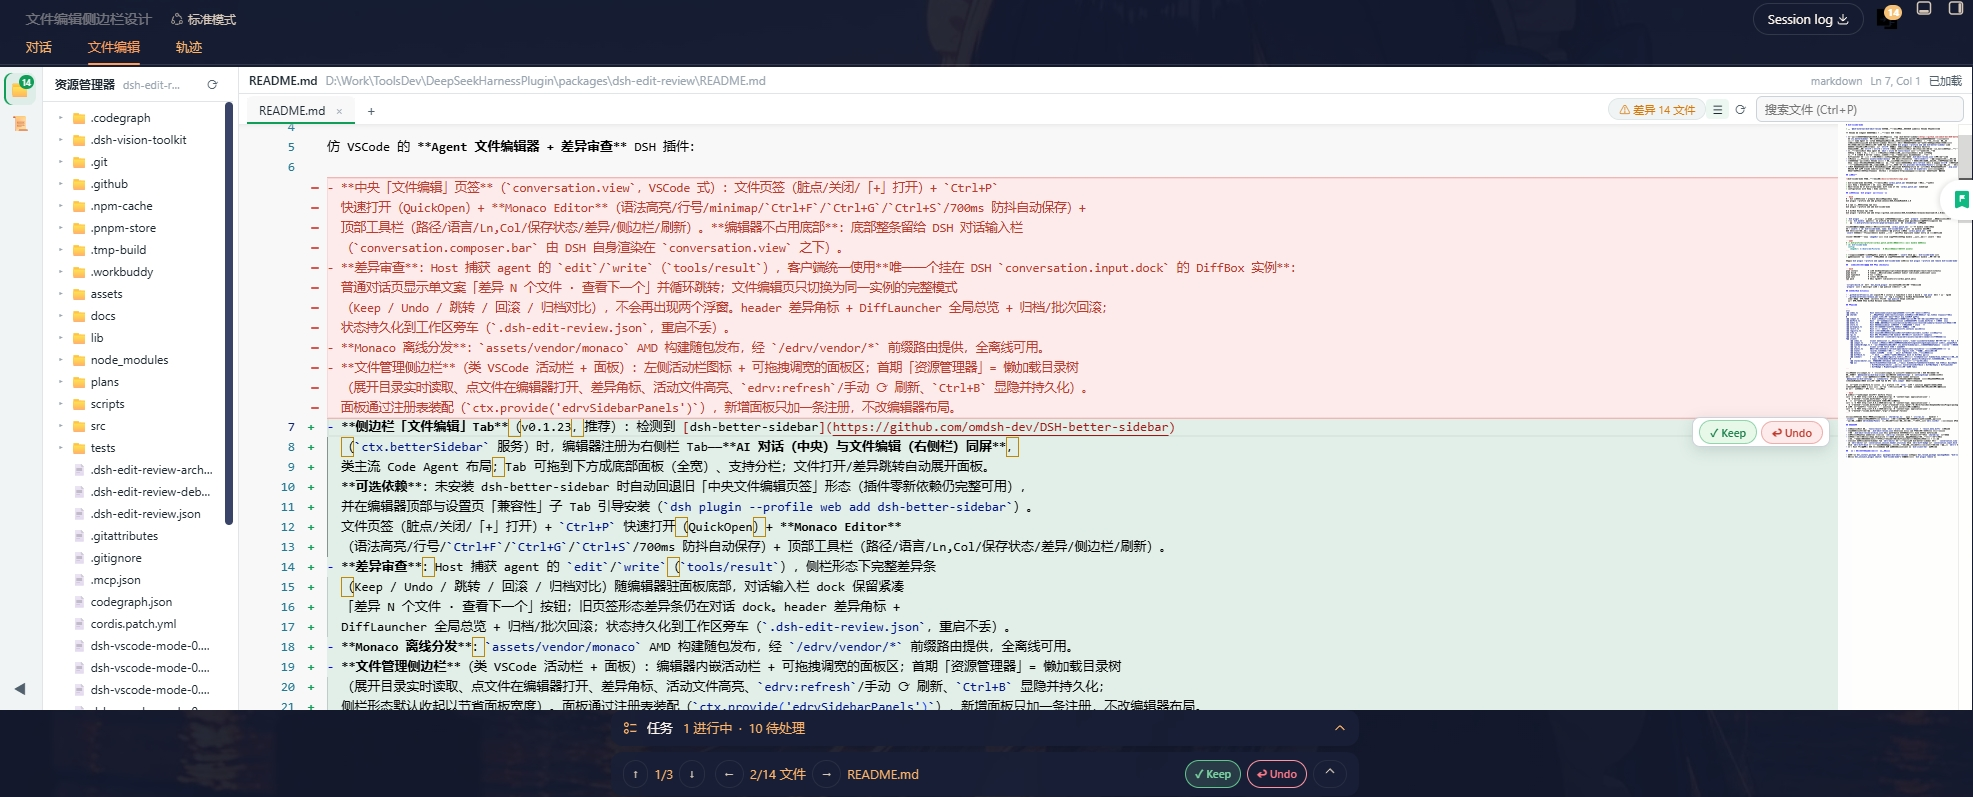
DSH_VsCodeMode is a DSH plugin that provides a VSCode-like coding experience, integrating file editor, diff review, file management, and performance optimization.
A DeepSeek Harness plugin that shapes oversized tool results before inference, offers a zero-cost mechanical fold as an alternative to LLM compaction, and optionally renders dense content to image for further token savings.