dsh-provider-rate-limit
Run the following command in DeepSeek Harness:
dsh plugin install jyao-SUSE-power-group/dsh-provider-rate-limit
Paste the following prompt into your AI chat to install this plugin:
Run dsh plugin install jyao-SUSE-power-group/dsh-provider-rate-limit in DeepSeek Harness to install this plugin. Source: https://github.com/jyao-SUSE-power-group/dsh-provider-rate-limit
About this plugin
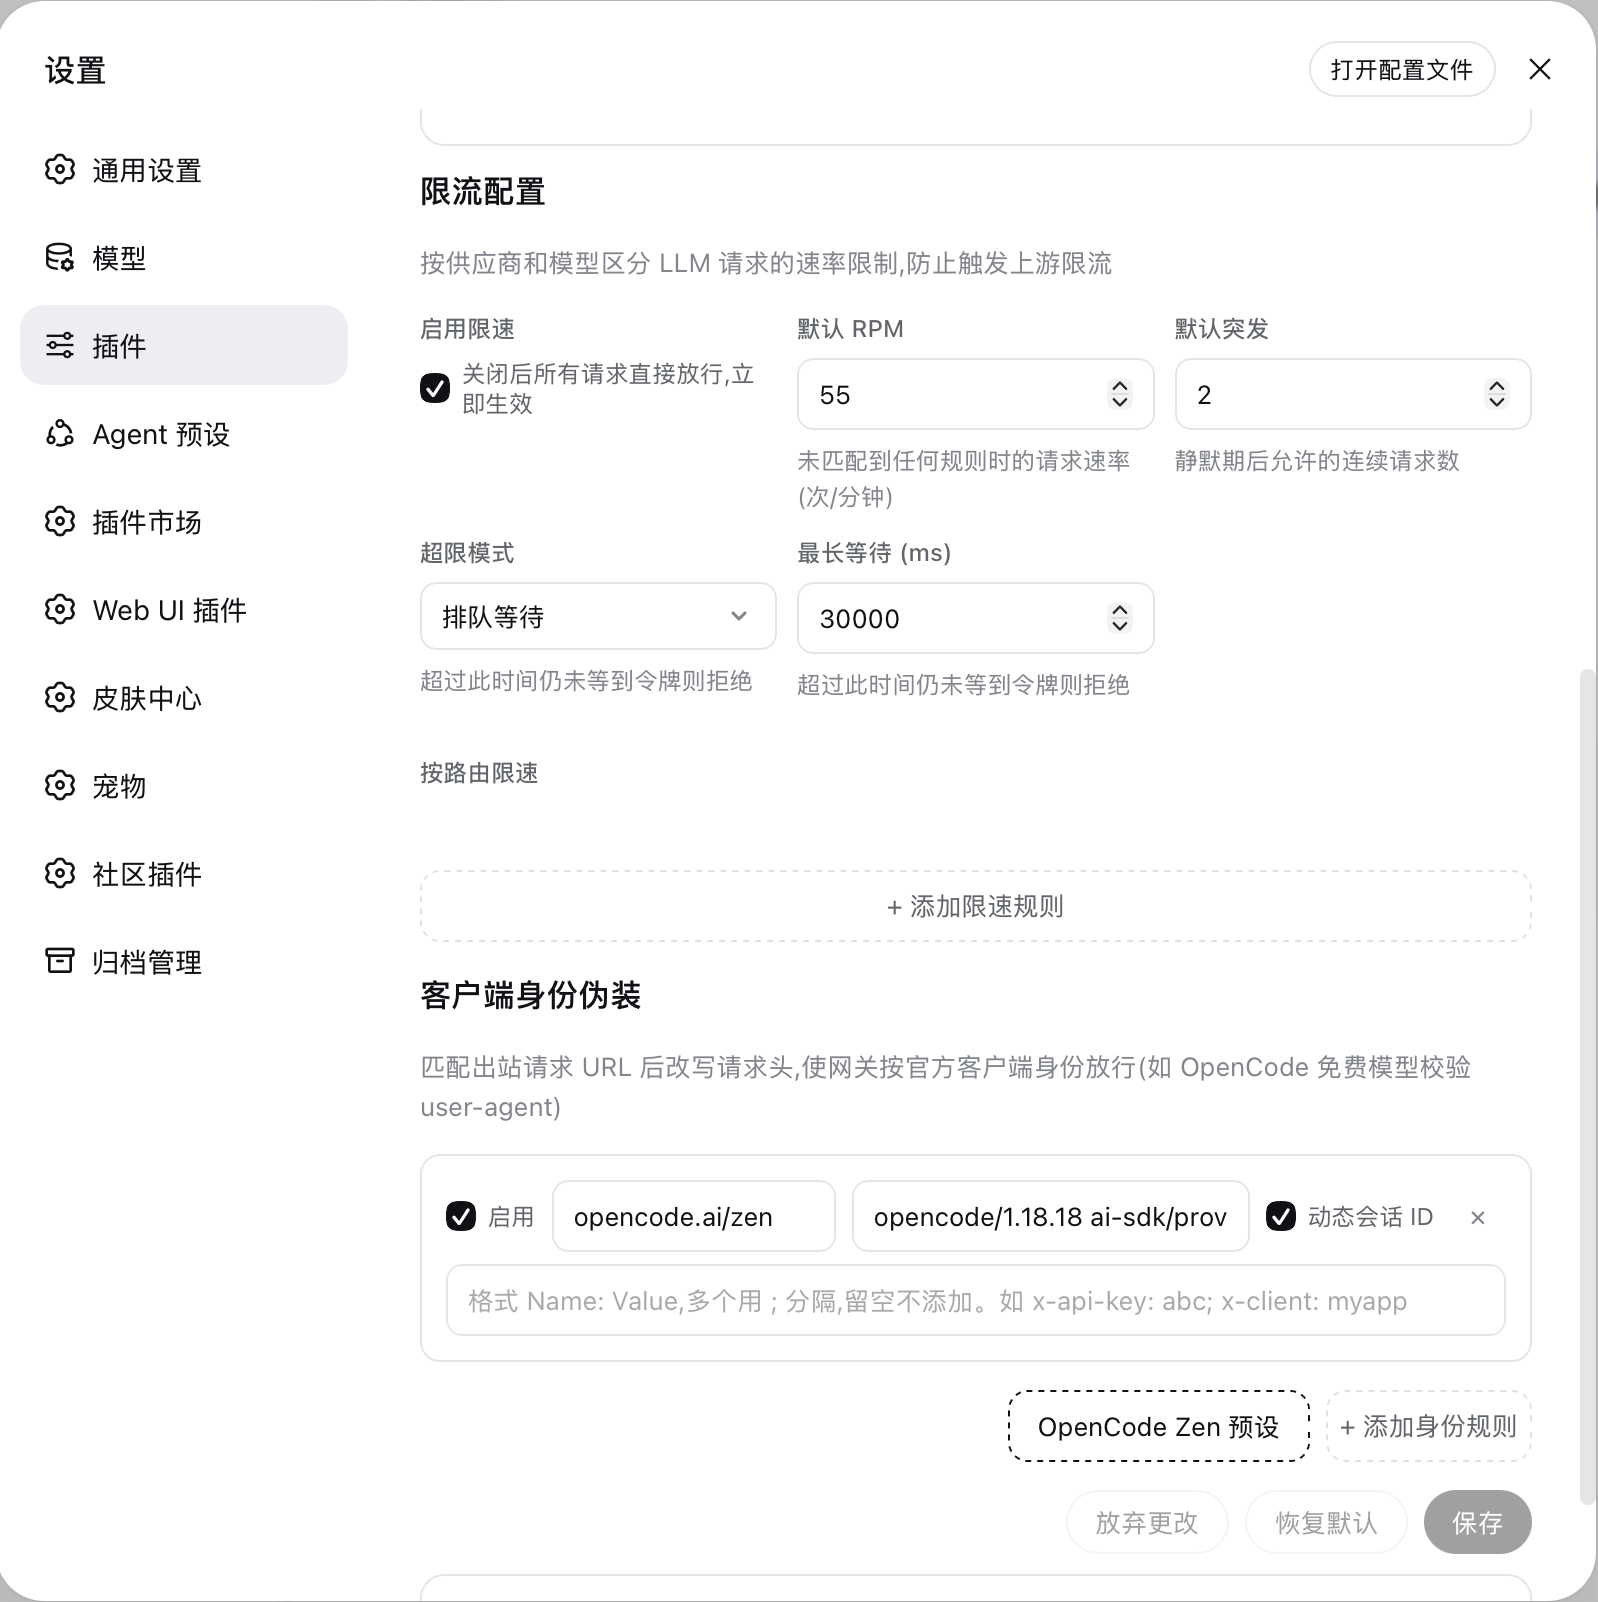
DeepSeek Harness lets you route LLM traffic through multiple providers simultaneously, but in practice free-tier gateways often return HTTP 429 when quotas are exhausted or reject requests outright because they cannot identify a legitimate client. Without per-provider or per-model throttling and graceful backoff, a burst of parallel agents can instantly burn through an upstream quota and take the entire pipeline offline.
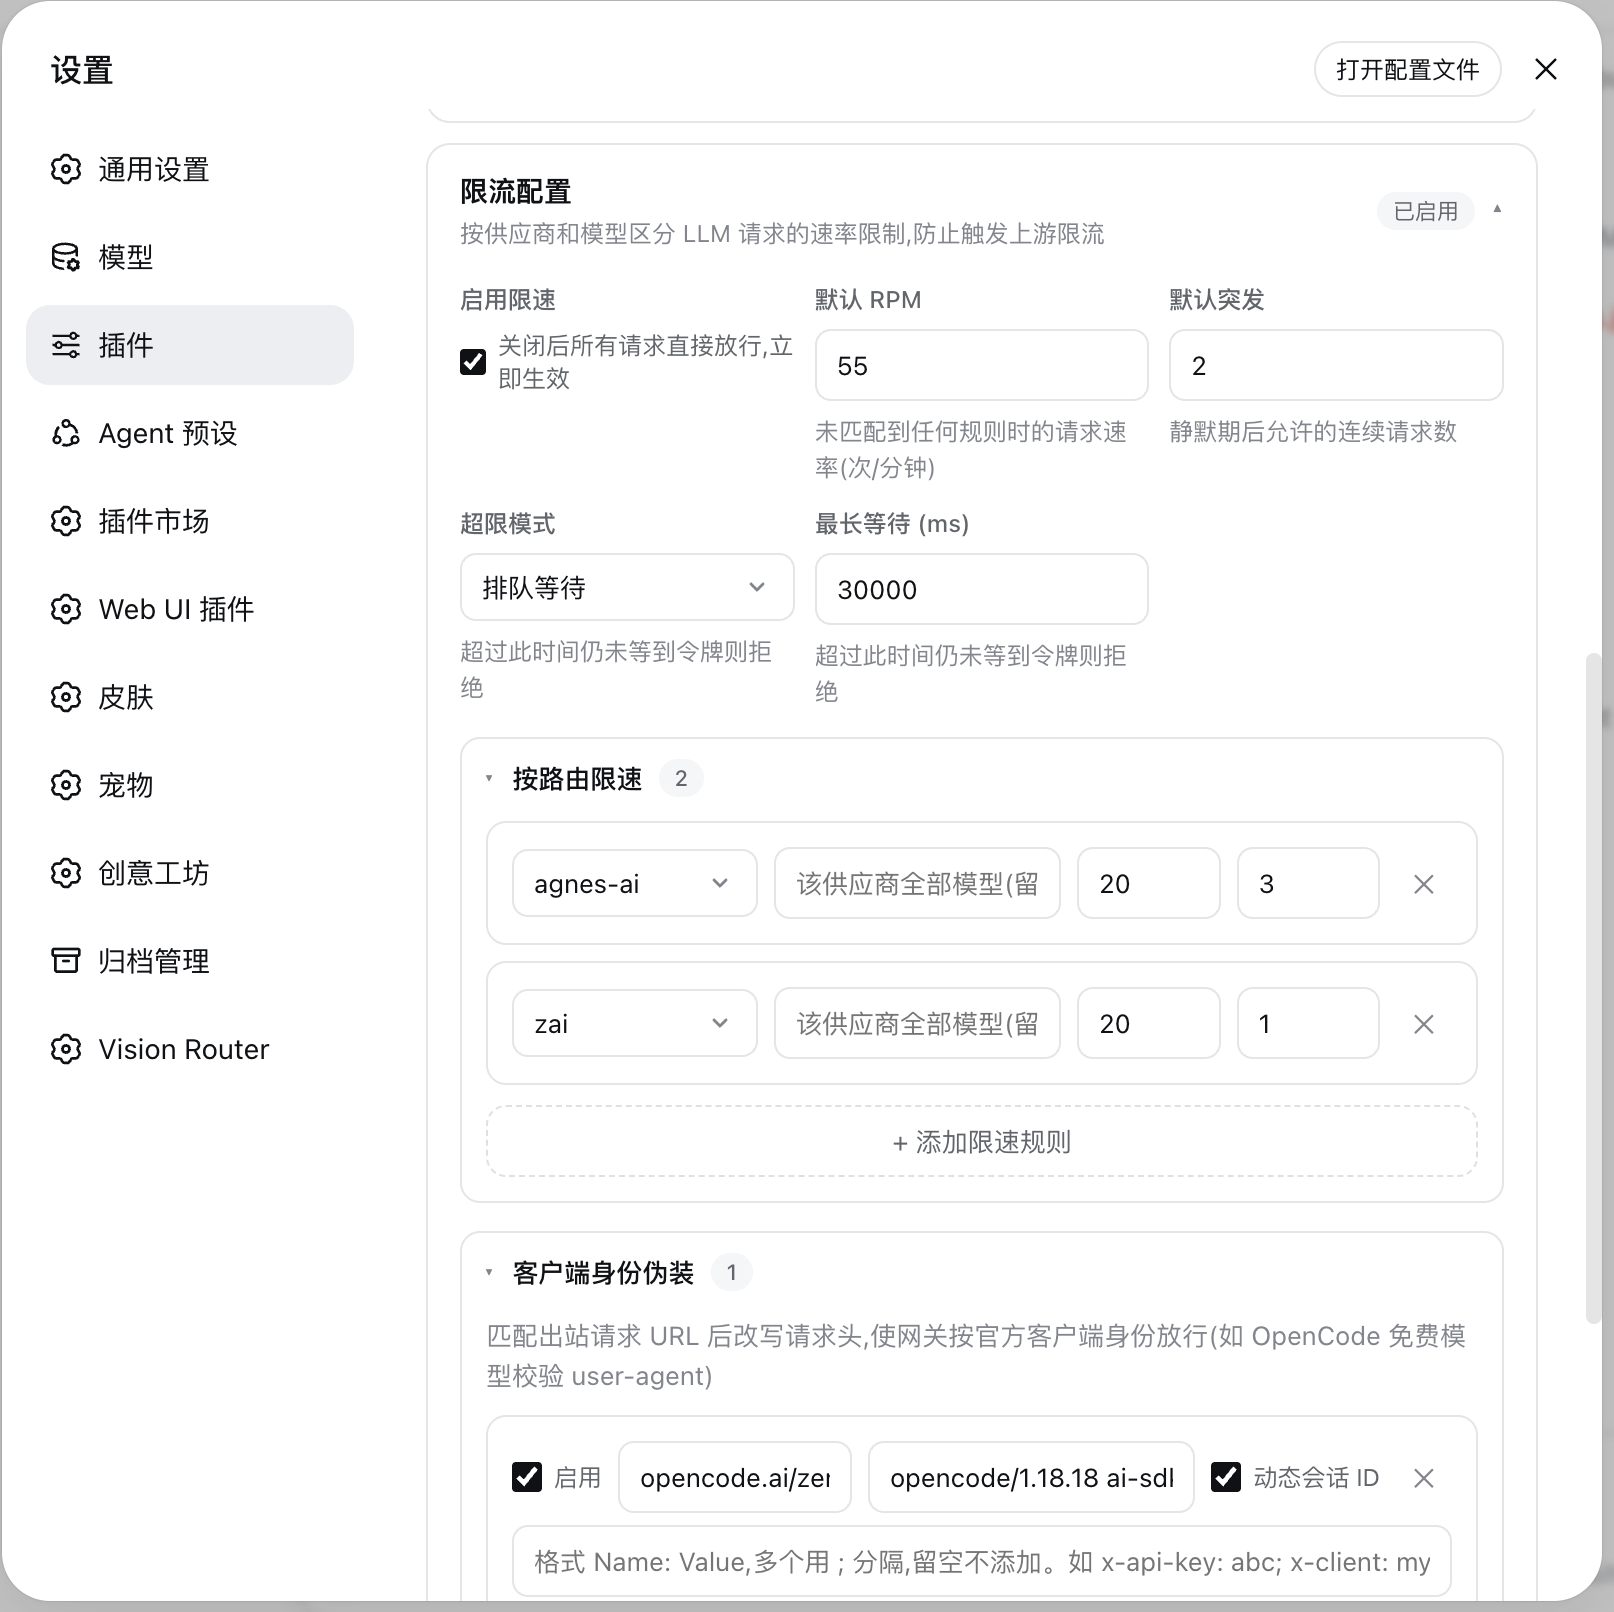
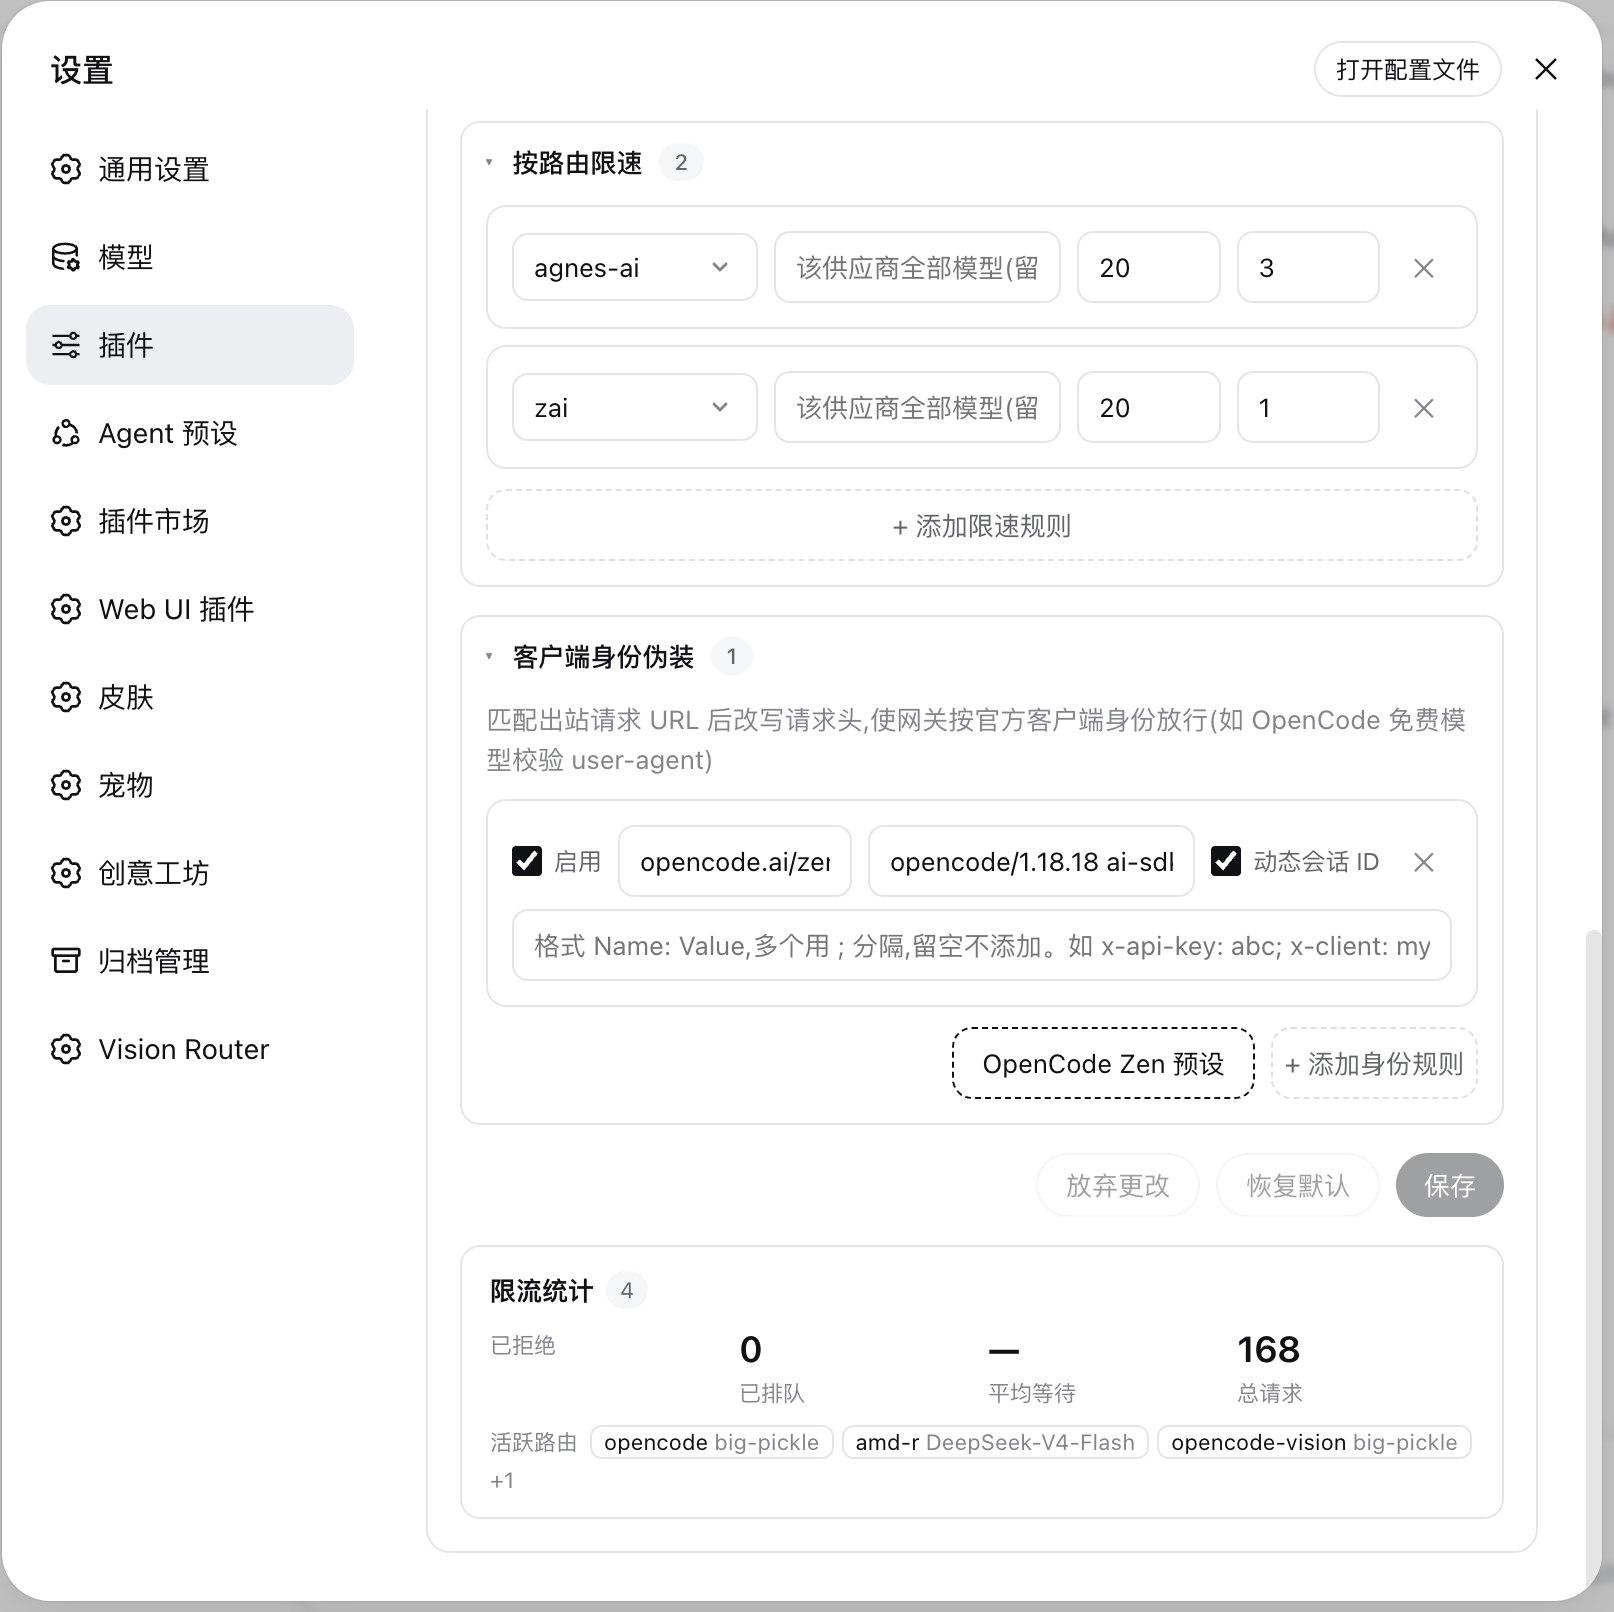
dsh-provider-rate-limit intercepts every outbound LLM stream at the llm/stream hook and enforces token-bucket rate limiting keyed by resolved provider and model, with configurable RPM, burst capacity, and a choice between queue-and-wait or fail-fast reject modes. When an upstream 429 arrives, the plugin enters an exponential-backoff cooldown window (with optional jitter) so the provider gets breathing room, and a concurrency cap prevents parallel sub-agents from overwhelming a route even when per-minute limits have not been reached. For identity-gated free gateways such as OpenCode Zen, built-in rules rewrite User-Agent and inject per-request dynamic headers, with a one-click preset for common setups.
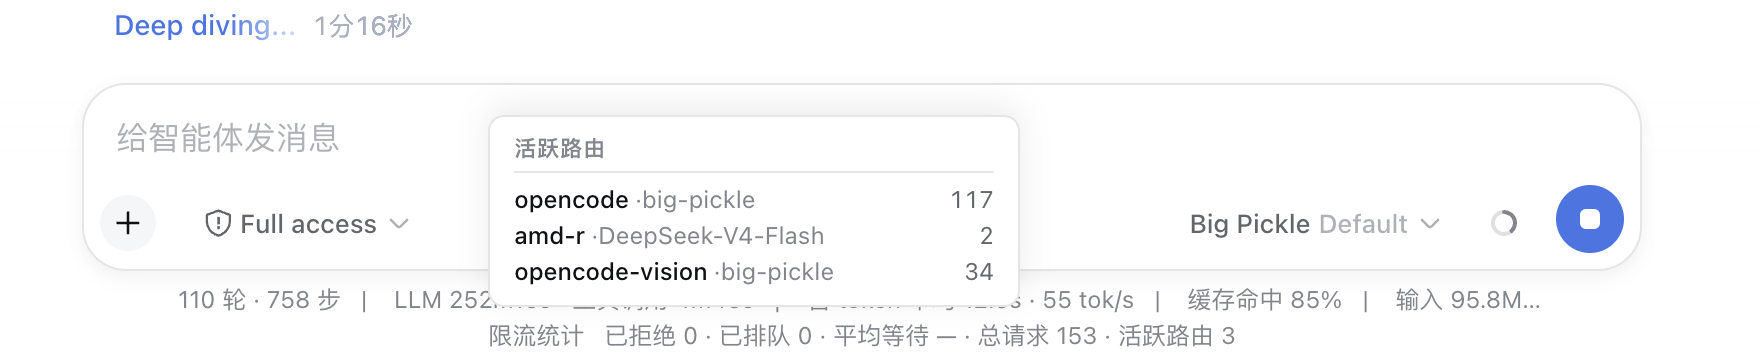
Ideal for DeepSeek Harness users who fan out to multiple LLM providers—especially those reliant on free-tier or quota-limited gateways—and who need differentiated per-model limits, real-time queue-depth visibility in the composer dock, or the ability to query rate-limit statistics from other plugins in-process.
Screenshots
Use Cases
- Preventing quota exhaustion when multiple agents call LLMs in parallel
- Free-tier gateways rejecting requests that fail client-identity checks
- Monitoring per-provider and per-model queue depth and reject counts in real time
Best For
- DeepSeek Harness users routing traffic to multiple LLM providers simultaneously
- Individual developers and small teams relying on free-tier or quota-limited gateways
- Integration developers who need to share rate-limit statistics across plugins in-process
Related Plugins

Adds an Auto approval mode on the official workspace-write sandbox, classifying semantic risks, asking when ambiguous, and denying destructive operations.

Undo/rollback system for DSH: config & plugin snapshots, one-click undo/redo/restore, message-level revert, secret masking, safe mode, and offline WebUI/GUI/CLI rescue tools for when DSH won't start.
Packages all 87 SKILL.md files from upstream reverse-skill as a DeepSeek Harness plugin that auto-registers them for authorized reverse engineering, penetration testing, and security research.
Dockyard DSH is a native DeepSeek Harness plugin that unifies official OAuth/client sessions for Codex, Antigravity, Grok, Claude, and Cursor, providing account pool, model catalog, and quota status.